Offline vs online evaluation for AI models: what actually matters

A model that scores well on your eval set and then degrades a production metric isn't a fluke — it's what happens when teams treat offline and online evaluation as two ways of measuring the same thing.
They aren't. Offline evaluation answers whether your model predicts historical data well. Online evaluation answers whether it actually improves outcomes for real users. Conflating them is the most common way AI evaluation programs produce confident answers to the wrong questions.
This article is for engineers, PMs, and data teams who are building or improving evaluation programs for AI models — especially those who have felt the gap between strong benchmark scores and disappointing production results.
Whether you're working with recommendation systems, LLM-powered features, or classification pipelines, the core problem is the same: eval datasets, automated scoring, and human review tell you one thing, and live user behavior tells you another. Here's what you'll learn:
- Why offline metrics don't guarantee real-world performance — and the specific structural reasons they fail
- What online evaluation actually costs in infrastructure, risk, and interpretive complexity
- How to sequence offline and online evaluation as decision gates, not parallel options
- How to choose the right metrics at each stage, including guardrail metrics that catch wins that aren't really wins
The article moves in that order — from understanding what each method measures, to why offline scores mislead, to the real demands of production experiments, to the sequencing and metric discipline that makes both stages reliable.
By the end, you'll have a clear mental model for when to trust your eval results and when to be skeptical of them.
What offline and online AI evaluation actually measure
Most evaluation debates inside engineering and product teams get stuck because people are arguing about methods when they should be arguing about questions.
Offline evaluation and online evaluation don't measure the same thing with different tools — they answer fundamentally different questions about fundamentally different realities. Until a team internalizes that distinction, their evaluation program will produce confident answers to the wrong questions.
Offline evaluation measures model performance against a fixed past
Offline evaluation measures model performance against a fixed dataset using a defined scoring method. You hold out a slice of historical data, score your model's predictions against labeled ground truth, and compare results across model versions. The question it answers is: does this model predict past data well?
This is the default starting point for most ML projects because it's repeatable, fast, and easy to compare. For tasks where correctness is clearly definable — classification, entity extraction, ranking, regression — offline evaluation works cleanly.
It's particularly valuable for regression testing: once you have a stable evaluation set, you can quickly detect whether a new model version improves or degrades performance before anything touches production. In recommender systems, for example, offline metrics like precision, recall, mean average precision (MAP), and normalized discounted cumulative gain (NDCG) give teams a consistent signal for iterating on model architecture without running live experiments.
The key constraint is baked into the definition: offline evaluation is always operating against historical data. It measures model quality in a controlled, static approximation of reality.
Online evaluation measures whether the model improves outcomes for real users
Online evaluation measures model performance in a live environment against real user inputs and real interaction patterns. The question it answers is: does this model improve outcomes for actual users?
That shift in question is not subtle. Online evaluation captures dynamics that no static dataset can represent: how recommendations influence user behavior and vice versa, how the model performs under real latency conditions, how it handles the long tail of inputs that never appeared in your training or evaluation data.
The canonical online method is A/B testing — one user segment receives the new model, another receives the existing system, and you track behavioral metrics like click-through rate, conversion rate, or time on platform. These metrics connect model behavior directly to user outcomes and business objectives.
Online evaluation requires infrastructure to segment users, track interactions, and ensure statistical validity. It is slower, costlier, and riskier than offline evaluation. But it answers the question that actually determines whether a model ships.
The gap is ontological, not methodological
The gap between offline and online AI evaluation is not methodological — it's ontological. They are measuring different things. As Shaped.ai puts it directly: "predicting a hold-out set of interactions is not the same as predicting what your users will actually interact with."
Here's what that gap looks like in practice. A team trains a new recommendation model, evaluates it on a chronologically split hold-out set, and sees improved NDCG scores. They conclude the model is ready and ship it. In production, CTR drops.
What happened? The model overfit to historical interaction patterns that have since shifted — seasonal behavior changed, the content catalog expanded, user intent evolved. The offline scores were real. The production degradation was also real. Both can be true simultaneously because they're measuring different things.
This failure mode — mistaking strong offline scores for production readiness — is the most common and consequential mistake in AI evaluation programs.
Conflating the two questions fails teams in opposite directions
Teams that conflate these two questions tend to fail in one of two directions. They either stop at offline evaluation and ship prematurely, trusting that good scores on historical data predict good behavior in production. Or they skip offline evaluation entirely and run expensive, risky online experiments on model candidates that could have been filtered cheaply before touching users.
The correct mental model treats offline and online evaluation as sequential decision gates, not interchangeable alternatives. Offline evaluation is the filter that keeps weak candidates from consuming online experiment slots. Online evaluation is the confirmation that improvements actually hold when real users encounter them. Neither works without the other, and neither substitutes for the other.
GrowthBook's framing captures the relationship well: "When it comes to AI, evals are just the tip of the iceberg. A/B testing is where real value gets created." Landon Smith, Head of Post-Training at Character.AI, describes using A/B testing to "compare different modeling techniques from the perspective of our users" — which is precisely the move from model-quality evaluation to user-outcome evaluation that the offline-to-online transition represents.
The rest of this article builds on that distinction. But if you take one thing from this section: offline eval answers whether your model is good at predicting the past. Online eval answers whether it makes things better for the people using your product. These are not the same question, and treating them as such is where evaluation programs go wrong.
Why strong offline metrics don't guarantee real-world performance
If you've ever shipped a model that looked great on your eval set and then watched it land flat — or worse, degrade a production metric — you've already encountered the core problem this section is about.
The frustration is real, and it has specific causes. Understanding them is more useful than simply running more offline tests.
The dataset approximation problem
Every offline evaluation dataset is a historical artifact. It captures what users did interact with, under the conditions that existed when the data was collected, with the system that was running at the time. That's a fundamentally different thing from what your users will interact with under a new model.
The gap isn't a flaw in your data collection — it's structural. Fixed datasets underrepresent edge cases by definition, because edge cases are rare. They omit new user behaviors that didn't exist when the data was collected. And they reflect the decisions of the previous system, not a neutral sample of user intent.
Two biases compound this problem in recommendation systems, but the underlying dynamic applies broadly. First, your eval set only contains interactions with items that were actually shown to users — if the old model never surfaced a particular item, that item has no interaction data, so the new model is being evaluated against a sample the old model already shaped.
Second, users click on things in prominent positions more than things buried lower on the page, regardless of actual quality — which means your historical data overrepresents whatever the previous system ranked highly. Both biases point in the same direction: offline data reflects past system decisions, not neutral ground truth about what users actually want.
Distribution shift over time
Even a well-constructed offline dataset decays. User preferences shift. Content catalogs change. Product contexts evolve. A dataset that accurately represented your production distribution shift six months ago may be meaningfully stale today.
The practical discipline here is chronological hold-out splitting — evaluating on data that comes after your training window rather than randomly sampled from the same period. Many teams skip this, which introduces time-based data leakage and produces optimistic offline scores that don't survive contact with live traffic.
And even teams that do split chronologically face a compounding problem: the gap between the most recent training data and live production widens continuously after deployment. There's no static fix.
The rubric design challenge for subjective outputs
For tasks with clear ground truth — classification, extraction, named entity recognition, ranking against explicit relevance judgments — offline evaluation is on solid footing. The problem sharpens considerably when the output is subjective.
As Label Studio notes: "Offline evaluation also struggles with metrics that require subjective judgment (tone, helpfulness, policy adherence) unless you've designed a rubric and labels that capture those qualities reliably." For chatbot responses, summaries, or any output where quality involves nuance, automated scoring produces numbers that may have no meaningful relationship to what users actually experience.
Practitioners building with tools like Promptfoo, Braintrust, and Opik are actively working on this — but the Hacker News community that uses these tools is candid about the limits. One practitioner reported that Promptfoo "broke down when we wanted evaluations with too many independent variables." Another summarized the state of agentic AI evaluation at many organizations as "vibes and logs." That's not a dismissal of offline eval — it's an honest acknowledgment that the methodology hasn't kept pace with the complexity of modern AI outputs.
When offline metrics are and aren't trustworthy
The practical decision rule is roughly this: offline metrics are reliable when you can define correctness independently of user behavior. Classification tasks, extraction tasks, ranking tasks with stable relevance judgments — these fit well.
Offline metrics become unreliable when the dataset isn't chronologically split, when output quality is inherently subjective, when the deployment environment differs significantly from the training distribution, or when "correct" is itself a function of what users do.
A model can score better on every offline metric and still cause new problems in production — particularly when the deployment environment is noisy, user inputs have shifted, or the evaluation rubric never captured what users actually care about. Offline metrics are necessary. They're not sufficient, and treating them as sufficient is the most common way evaluation programs mislead the teams relying on them.
The real costs and risks of running AI evaluation in production
Online evaluation is not a free upgrade from offline evaluation. It captures things offline cannot — but it does so at a cost in infrastructure, risk, and interpretive complexity that teams consistently underestimate until they've been burned by it.
The gap between a model that looks great in a notebook and one that holds up under production traffic and real users is precisely what online evaluation exists to close, and precisely why it demands more care than most teams initially plan for.
What online evaluation captures that offline cannot
The fundamental advantage of online evaluation is that it operates on real inputs from real users in real time. Offline datasets, no matter how carefully curated, are static approximations of a distribution that is constantly shifting. Online evaluation, by contrast, reflects current user behavior — including long-tail inputs, adversarial edge cases, and interaction patterns that never appeared in your training or evaluation data.
This matters for several reasons that don't show up in benchmark scores. Latency under load behaves differently than latency in a test harness. Users respond to model outputs in ways that create feedback loops — clicking, abandoning, rephrasing — that reveal quality signals no labeled dataset can replicate.
And distribution shift, the gradual drift between the world your model was trained on and the world it now operates in, is only detectable once the model is actually running against live traffic. Offline evaluation is structurally blind to all of this.
Shadow deployments, gradual rollouts, and A/B tests carry different risk profiles
There is no single approach to online evaluation — the right method depends on how much risk you're willing to accept and how much signal you need.
Shadow deployments are the lowest-risk entry point. The new model runs silently alongside the production model, scoring the same inputs without exposing users to its outputs. You compare results across real traffic before any user sees a difference. This is useful for catching gross failures before they reach production, but it doesn't tell you how users would actually respond to the new model's behavior.
Rather than treating gradual rollouts as a middle step to skip, teams should recognize them as the primary mechanism for learning from real behavior while containing risk. A phased rollout exposes the new model to a small, controlled percentage of real users, then expands incrementally as engagement data confirms the model is performing as expected — balancing real-world signal with a limited blast radius for any failure.
A/B tests are the highest-signal method and the highest-risk. A defined treatment group receives the new model while a control group receives the existing one, and you measure the difference in business metrics — impressions, clicks, conversion, task completion rates, depending on your product context.
For recommender systems specifically, this is the standard gate between offline validation and production deployment. A/B tests give you the cleanest causal read on business impact, but they require sufficient traffic, sufficient time, and sufficient discipline to interpret correctly.
Novelty effects, small samples, and confounds make online results easier to misread than they look
Running online experiments cleanly is harder than it looks. Three failure modes recur often enough to treat as defaults rather than edge cases.
Novelty effects distort early results. Users behave differently when they first encounter a changed model — sometimes better, sometimes worse — in ways that don't reflect steady-state behavior. Scaling a rollout too quickly based on early signal is a common way to lock in a misleading result. The guidance to start with small traffic percentages and scale only as wins persist reflects hard-won experience with this pattern.
Insufficient sample sizes are a related problem. The pressure to ship creates pressure to call experiments early. An experiment that looks like a win at 10% traffic may reverse at 50% when the sample becomes more representative of the full user population.
Confounding variables are harder to control in production than in a notebook. Seasonality, concurrent product changes, and external events can all contaminate results in ways that are difficult to detect after the fact. Online experiments work on averages, which means they can also mask harm to specific user subsets even when aggregate metrics look healthy.
Guardrails and rollback capability are what separate responsible online eval from naive online eval
Given these risks, responsible online evaluation requires more than good intentions. Infrastructure load testing before any online eval begins is a prerequisite, not an afterthought — you need to know your system can handle the new model's latency profile under real traffic before users depend on it.
Gradual rollout percentages should start small and expand only when the data supports it. Guardrail metrics — secondary metrics that must not degrade even if the primary metric improves — provide an automated check against the averaging problem. If your primary metric is task completion rate but your guardrail is error rate, a model that improves completions by routing users around failures will trip the guardrail before it ships widely.
Instant rollback capability is the final safety layer. The ability to deactivate an underperforming model immediately, without a deployment cycle, is what makes gradual rollouts genuinely low-risk rather than just incrementally slow.
Teams at companies like Character.AI have used this combination of gradual exposure and real-time model comparison to guide research decisions based on actual user outcomes — not just eval scores. That combination of controlled exposure, live measurement, and fast rollback is what separates online evaluation done responsibly from online evaluation done naively.
The sequence between offline and online evaluation has a directional logic that teams routinely ignore
Offline and online evaluation are not competing philosophies you choose between based on team preference or resource constraints. They are sequential stages of a single evaluation program, and the sequence has a directional logic that matters.
Offline is fast and cheap — it gives you iteration speed and regression safety. Online is slow and expensive — it gives you confirmation that improvements actually hold against real users and real business outcomes. Running them out of order, or treating them as parallel options without a gate between them, wastes resources in both directions.
As Label Studio puts it directly: "Offline testing gives you repeatability and fast iteration. Online testing gives you confidence that those improvements hold in production." That's not a preference statement — it's a description of what each method is structurally capable of delivering.
Treat the sequence as a discipline, not a default
The reason teams collapse offline and online evaluation into a single undifferentiated process is usually speed pressure. A new model version looks promising, the team wants to ship, and the offline eval feels like a formality before the "real" test in production.
This logic inverts the cost structure. Online experiment slots are finite, slow to run, and carry real user risk. Spending them on candidates that could have been eliminated with a cheap offline regression test is a process failure, not a shortcut.
The sequence should be treated as a gate, not a guideline. Candidates that regress on the offline evaluation set don't advance to production testing. Full stop. This discipline is what makes the online stage meaningful — by the time you're running a production experiment, you've already filtered out the noise.
The offline filtering stage: eliminate before you validate
Offline evaluation's primary role in the sequence is elimination. Its value is not in telling you which model is best — it's in telling you which candidates are not worth testing against real users. Because offline scoring is repeatable and fast, you can evaluate multiple model versions in parallel before any user is exposed to any of them.
This is where regression benchmarks earn their keep. A stable evaluation set lets you quickly surface whether a new model version degrades on behaviors the previous version handled correctly — a capability that's genuinely difficult to replicate in production without exposing users to regressions.
The offline stage is also where automated scoring for well-defined tasks (classification accuracy, extraction quality, ranking performance) provides the most reliable signal, because the ground truth is clear and the measurement is consistent across runs.
The key discipline here is defining the offline pass threshold before you start scoring. Teams that define "good enough" after seeing the results are optimizing for confirmation, not evaluation.
The online validation stage: confirm against real behavior
Once candidates pass the offline gate, online experiments answer the question that offline cannot: do these improvements hold when real users, with their actual distribution of inputs and intentions, interact with the model under production conditions?
This stage should begin conservatively — a small initial traffic percentage, expanded incrementally based on engagement data. Gradual rollout tooling is built for exactly this pattern, allowing teams to roll out model changes incrementally while monitoring whether the expected improvements materialize at scale.
Equally important is the ability to roll back instantly if a candidate that looked strong offline starts degrading production metrics — that rollback capability is what makes teams willing to run online experiments at all.
One practical tool for the online stage worth knowing about: sequential testing allows teams to monitor experiment results continuously without inflating false positive rates. In a standard A/B test, you set a required sample size before you start and wait until you hit it — calling the experiment early inflates your false positive rate.
Sequential testing is designed to let you check results continuously and stop as soon as you have enough evidence to decide, without that statistical penalty. For teams running many model experiments, this can meaningfully compress decision timelines.
Define stage-appropriate metrics before you start
The sequencing only works if the metrics governing each stage are defined before evaluation begins. Offline metrics — automated scoring, regression benchmarks, ranking quality measures — govern the filtering stage. Online metrics — task completion rates, engagement signals, conversion — govern the validation stage. These are different questions answered by different instruments, and conflating them at either stage produces noise.
The transition between stages is also the moment to define guardrail metrics for the online experiment: the metrics that must not degrade even if the primary metric improves. A model that lifts average engagement while degrading performance for a user subset, or that improves a headline metric while increasing latency, has not passed online validation — it has passed a partial test. Guardrail metrics are what make the online stage a genuine confirmation rather than a selective one.
As GrowthBook's A/B testing guidance frames it: "When it comes to AI, evals are just the tip of the iceberg. A/B testing is where real value gets created." That framing captures the sequencing logic precisely — offline evals are necessary, but they're the filter, not the verdict.
Metric selection is where AI evaluation programs quietly fall apart
Metric selection is where most AI evaluation programs quietly fall apart. Teams pick metrics that are easy to compute, not metrics that answer the question they actually care about.
The result is a feedback loop that optimizes for measurement convenience rather than model quality or user outcomes. Getting this right requires treating offline vs. online AI evaluation as distinct measurement contexts — each with its own appropriate signals, failure modes, and design constraints.
Offline metrics work best when correctness is definable
Offline evaluation produces reliable signals when you can draw a clear line between right and wrong. Classification, extraction, detection, and ranking tasks fit this profile well: you can build a labeled evaluation set, score model predictions against it, and trust that an improved score reflects a genuinely better model.
The critical qualifier is that "correctness" must be unambiguous. The moment outputs become interpretive — a summary that's technically accurate but poorly structured, a recommendation that's relevant but not personalized — offline metrics require additional scaffolding to remain valid. Without it, you're scoring something that doesn't map cleanly to what you care about.
The rubric design problem for subjective AI outputs
Generative AI outputs break the assumptions that make offline metrics tractable. Tone, helpfulness, and policy adherence can't be scored reliably without a deliberately designed rubric and labeled examples. As Label Studio puts it directly: "Offline evaluation also struggles with metrics that require subjective judgment (tone, helpfulness, policy adherence) unless you've designed a rubric and labels that capture those qualities reliably."
The rubric doesn't emerge from the dataset — it requires intentional investment in defining what "good" looks like, building labeled examples through human review, and validating that raters apply the rubric consistently.
Skip any of those steps and your automated scoring produces a number that feels rigorous but measures something loosely correlated with quality at best. This is the core reason offline benchmarking for LLM outputs remains genuinely hard: the measurement problem isn't solved by having more data, it's solved by having better-defined criteria.
Online metrics must connect to user outcomes
Online metrics should not measure model behavior in isolation. The question isn't whether the model produces better outputs in the abstract — it's whether users accomplish more, engage more meaningfully, or achieve better outcomes because of the model. The right orientation is data that links directly to user outcomes: the metric should be downstream of the model, not a proxy for it.
What that means in practice depends on product context. A search system cares about whether users find what they're looking for — impressions and clicks are a starting point, but task completion and query reformulation rates tell a more honest story. A conversational assistant should be measured on whether users successfully accomplish what they came to do.
A content recommendation system might track session depth or return visits. The specific metric matters less than the discipline of asking: does this number reflect what users actually got out of the interaction?
Landon Smith, Head of Post-Training at Character.AI, described the value of this orientation directly: "We can compare different modeling techniques from the perspective of our users — guiding our research in the direction that best serves our product." That framing — model decisions evaluated through user outcomes — is the right mental model for online metric selection.
The averaging problem and subset harm
Aggregate experiment results are averages, and averages hide a lot. A model change that improves the primary metric across the full user population can simultaneously degrade the experience for a specific subgroup — and that harm won't surface unless you're explicitly measuring for it.
GrowthBook's experimentation documentation is unusually candid on this point: "Experimentation results work on averages, and this can hide a lot of systemic biases that may exist. There can be a tendency for algorithmic systems to 'learn' or otherwise encode real-world biases in their operation, and then further amplify/reinforce those biases."
Short-term metric gains compound this problem. Optimizing for engagement or conversion without tracking longer-term signals can produce what looks like a win but is actually a dark pattern — "where you inadvertently exploit user trust to boost numbers temporarily at the expense of long-term retention." The metric was right; the measurement window was wrong.
The practical response is to segment experiment results by meaningful user dimensions and define in advance which subgroup outcomes you're committed to protecting. This isn't just an ethical consideration — it's a measurement validity concern. A result that improves the average while harming a subgroup is not a reliable signal that the model change was good.
Guardrail metric design
Guardrail metrics exist to catch the cases where a primary metric improves while something else quietly degrades. They're not secondary metrics — they're constraints on what counts as a valid win.
The clearest illustration of why they matter is the revenue-versus-retention pattern: an experiment drives purchasing behavior, the revenue metric goes up, and the team ships the change — but retention is declining in parallel, indicating that the purchasing behavior was extracted at the cost of user trust.
GrowthBook's Metric Correlations feature surfaces exactly this kind of trade-off, flagging when experiments are driving purchasing behavior while simultaneously making the product worse. Without a guardrail metric on retention, that signal gets missed entirely.
Guardrail metrics also play a structural role in safe rollout design. Connecting rollout decisions to warehouse-backed guardrail metrics — with automated rollback triggers when those metrics breach defined thresholds — turns guardrails from a post-hoc analysis concern into an active safety mechanism.
The discipline of defining guardrail metrics before an experiment runs, not after results come in, is what separates evaluation programs that catch problems from those that rationalize them.
Putting it together: the evaluation logic that holds under pressure
The core argument of this article is simple, even if the execution isn't: offline and online evaluation answer different questions, and your program only works if you treat them that way.
Offline eval is a filter — fast, cheap, and essential for catching regressions before they reach users. Online eval is a confirmation — slow, expensive, and the only way to know whether your improvements actually hold against real behavior. The sequence matters. The gate between them matters. And the metrics you define at each stage, before you start scoring, are what determine whether your results are trustworthy or just reassuring.
Most evaluation programs fail because they're rigorous about the wrong question
Before you pick a method or a metric, get clear on what you're actually asking. "Is this model better?" is not a question — it's two questions wearing the same coat. Better at predicting historical data? Better at producing outcomes for real users?
Those require different instruments, different timelines, and different standards of evidence. Most evaluation programs go wrong not because teams lack rigor, but because they're rigorous about the wrong question.
When offline signal is trustworthy and when it isn't: a decision rule
If your output has a clear ground truth and your dataset is chronologically split, offline metrics will give you reliable signal. If your output is generative or subjective, you need a rubric before your offline scores mean anything.
And if your offline metrics look strong but you haven't confirmed against live traffic, you have a promising candidate — not a shippable model. The transition from offline to online isn't a formality; it's the moment you find out whether your eval set was actually measuring what matters.
The minimum viable evaluation stack for AI product teams
You don't need a sophisticated evaluation program to start. You need a stable offline eval set with a defined pass threshold, a way to run gradual rollouts against real users, and at least one guardrail metric that tells you when a headline win is hiding a loss somewhere else.
A combination of feature flags, gradual rollouts, and warehouse-native metric tracking gives teams a practical foundation for the online stage without requiring a bespoke experimentation platform.
This article is meant to be genuinely useful — not just a framework to nod at, but a way of thinking you can apply to the next model decision your team faces.
What to do next: Start by auditing your current offline eval set. Ask two questions: Is it chronologically split, or randomly sampled? And does your pass threshold exist before you run scoring, or does it emerge after you see the numbers? If either answer is uncomfortable, fix that before you touch your online experimentation setup. A well-constructed offline gate is the highest-leverage improvement most teams can make — and it costs nothing to run.
Related insights
- AI Evals vs. A/B Testing: Why You Need Both to Ship GenAI
- Why Choose GrowthBook for Feature Flagging
- 8 Best Open-Source Feature Flagging Tools Compared
Related Articles
CLI vs MCP: TLDR, it doesn’t matter as much as you think
Your agent should know how to do the job whichever interface it uses.
Your coding agent can already run terminal commands. Your product manager's assistant can connect to remote tools. Both need to inspect the same experiment, understand the same metric, and prepare changes to the same feature flag.
That creates a familiar question: should you give them a CLI or an MCP server?
The usual answers mix several concerns. A CLI is easy to compose with scripts. MCP gives compatible clients a standard way to discover and invoke tools. Skills can supply the instructions that make either route useful. None of those statements tells you whether the agent knows your release process or can distinguish a draft from a live change.
For GrowthBook, the choice has become smaller. We've built the agent layer around a REST API and reusable workflow skills, then made those available through different interfaces. Your choice of CLI or MCP no longer needs to determine which product workflow your agent can understand.
It still determines how the agent connects, executes requests, and handles credentials. This article explains that distinction, shows the same disabled-flag operation through both routes, and gives you a way to evaluate the integration you actually intend to use.
The debate combines three different questions
Start with a specific job: prepare a release control for a new checkout flow. The agent needs to know which project owns checkout, which environments exist, what the default behavior should be, and whether the proposed flag key already exists.
Choosing an interface answers only part of that job.
How can the agent reach the product?
A command-line interface lets an agent invoke a program in an environment where it has shell access. That program can make authenticated API requests and return data. You can also run the same commands yourself, put them in scripts, and preserve output for inspection.
The Model Context Protocol architecture connects a host application to servers through clients. An MCP server exposes capabilities that a compatible host can discover and call. The host might be a coding environment, a desktop assistant, or another agent application.
These categories overlap. A terminal-based agent can also be an MCP client. A local MCP server can be a process launched by that client. A remote MCP connection can work without the host giving the model a general-purpose shell.
So “terminal agent” doesn't automatically mean “use the CLI,” and “MCP” doesn't automatically mean “remote service.” Ask what access the runtime provides before choosing the adapter.
What procedure should the agent follow?
An API can expose a create operation without teaching an agent when to use it. A syntactically valid feature flag might still have the wrong project, an ambiguous key, or a default value that doesn't match the application.
That's the job of a skill: reusable instructions for a recognizable task. The Agent Skills format gives those instructions a portable structure, including a skill entry point and supporting references. A workflow can describe the context to inspect, the sequence to follow, and the evidence to return.
For the checkout example, useful guidance says to resolve environments, check the permanent key, choose a value type, and create the flag disabled. Merely exposing a create command leaves those decisions to the agent's general knowledge.
Skills are also useful when the right answer is to take no action yet. “Create a flag” and “design an experiment” are related requests, but they can require different objects and sequencing. An agent needs enough product guidance to make that distinction.
What context makes the procedure relevant?
Even a good playbook needs the current product state. The agent should inspect the objects in your GrowthBook organization and, when it is changing application code, the repository's SDK initialization and tests.
Those are different sources of context. GrowthBook supplies flags, experiments, metric definitions, and other authorized product resources. Your coding runtime supplies the application files it can access. An MCP connection doesn't by itself grant repository access, and a CLI doesn't by itself explain your metric definitions.
Evaluate the combination: access to the product, a maintained procedure, and enough context to apply that procedure. A comparison that changes all three at once cannot isolate the effect of CLI versus MCP.
GrowthBook puts the durable parts below the interface
We separated the agent layer into responsibilities that can be reused. The product API exposes operations. Skills explain workflows. The interface connects the agent to those two layers.
This is the architectural shift behind GrowthBook's agent experience. Instead of making every client integration carry its own interpretation of experimentation, we can share the interpretation and change how it is delivered.
The API provides the operations
GrowthBook's REST API makes product objects addressable. An agent can inspect a project, retrieve a flag, or perform an authorized operation against those objects.
The rebuilt API described in GrowthBook 4.4 uses shared schemas to support types, validation, and API documentation. The CLI is generated from the API definition. That reduces the amount of separately maintained command logic needed to expose product operations.
The OpenAPI specification explains the underlying principle: a machine-readable description can represent an HTTP API's paths, operations, inputs, and responses. Generation is useful because it derives another interface from that contract.
Generation doesn't mean any installed binary knows every future endpoint. The generated client still has a version, and your GrowthBook server still has a version. A self-hosted instance can lag behind the public documentation. Treat API compatibility as a deployment fact you verify.
Skills provide the workflow guidance
GrowthBook's feature-flags skill routes requests to more specific workflows. Creating a flag, inspecting dependencies, changing targeting, requesting review, and publishing a revision are separate procedures.
That structure lets the agent load the guidance relevant to the current job. The skill authoring guidance on progressive disclosure supports this approach: keep the entry point focused and place detail in references that are loaded as needed.
The benefit is maintainability as well as context management. A correction to a flag workflow can be made in the maintained skill rather than repeated across a series of tool descriptions and client-specific prompts.
There are two shell concepts to keep distinct. The generated growthbook CLI is a terminal interface to the product API. The skills repository also includes a small gb-call helper for making REST requests. Installing a skill doesn't make that helper a globally available command; its location depends on the installation. Both can reach the API, but their configuration and invocation are different.
MCP provides a thin bridge
The current GrowthBook MCP implementation exposes four tools: growthbook_list_skills, growthbook_read_skill, growthbook_api_read, and growthbook_api_write.
An agent discovers a domain, reads the relevant workflow, then makes API calls. It doesn't need a dedicated MCP tool for every product endpoint. Calls described as gb-call GET in a skill map to the read tool; mutating methods map to the write tool with the same path and body.
The bridge does not run the shell helper. It forwards authenticated requests. Product-side permissions and validation remain important because a small tool surface can still reach many operations.
Shared guidance also has a delivery boundary: the MCP server bundles skills when it is built, using a pinned source revision. A newly edited skill in the repository needs to be included in a subsequent server build before that server supplies it. “Shared source” is a maintainability claim, not a promise of instant synchronization.
Explore the shared flag workflows
Open the feature-flags skill to see the procedures that guide creation, targeting, reviews, and publishing. Bring the same workflow knowledge to the agent interface your team uses.
View the Flag Skill
The same disabled flag can use either route
The practical question is whether the interface changes the job. Let's create a Boolean flag called checkout-redesign, with a false default and every environment disabled.
This is an API example for a sandbox project, not an application integration tutorial. It creates a control object; your application still needs a correctly configured GrowthBook SDK to evaluate it. The feature flag documentation covers the product concepts behind that integration.
Connect and verify before preparing the write
For the terminal route, install the current GrowthBook CLI, configure a Personal Access Token through its interactive setup, and inspect the available command syntax:
Check that the active server and identity are the ones you intend to use. Prefer a tested, pinned CLI version in repeatable automation. Don't include a live token in a command you plan to share.
For an MCP route, the GrowthBook Cloud setup uses the hosted endpoint and browser OAuth. In a client using the documented mcpServers configuration shape, such as Cursor, add:
Complete the browser authorization and confirm tool discovery. Other clients can use a different configuration shape. Self-hosted GrowthBook users should follow the local stdio or self-hosted HTTP instructions rather than point a private instance at the Cloud service.
Next, let the connected agent discover the flag-creation workflow. These are tool-call parameters, shown separately in the order to invoke them:
The returned guidance should describe the prerequisites for creating the flag. If the workflow isn't present, resolve the server's bundled skill version before substituting instructions from an older integration.
Resolve real IDs and construct one payload
The flag-creation workflow checks existing keys, lists projects, and resolves environments. In the MCP client, invoke the read tool with each of these argument objects:
For the CLI route, perform that discovery with the corresponding command groups documented in the CLI command catalog:
Inspect each command's help if your installed version differs. The returned keys, project IDs, and environment IDs are the inputs to the payload below. In MCP, the equivalent read-tool arguments are:
Verify that checkout-redesign isn't taken, identify the sandbox project's ID, and enumerate every actual environment. These read responses determine the payload; don't treat example environment names as a complete inventory of your organization.
Save the following as flag.json, replacing <PROJECT_ID> and the environment keys with the discovered values. This example assumes the only environments are staging and production:
The API represents defaultValue as a string, even for a Boolean flag. Explicitly disabling each environment avoids relying on the organization's default state for newly created flags. Use a PAT for this example so the caller has a user identity for attribution.
Review the permanent key, project, value, and disabled states before submitting. If the intended job is an experiment, route to experiment design first instead of creating an unrelated flag and hoping to connect it later.
Submit once, then read the object back
With the CLI, the create command accepts a JSON body. In a Bash-compatible shell, inspect the request with dry run before submitting:
The first command previews a request; it doesn't prove the server will accept it. Run the second only after checking the preview and approving this creation. In PowerShell, use that shell's file-reading syntax rather than paste the Bash substitution unchanged.
The PowerShell equivalent, using the same reviewed file, is:
The same distinction applies: preview first, approve the specific creation, then submit. Neither command changes the application's deployed code.
Through MCP, call growthbook_api_write with the same payload serialized into its body string. Substitute the same resolved project and environment names:
Choose one creation route. Don't run both against the same key; they target the same product object, and the second creation should encounter an existing key.
Verify through the CLI get command:
Or invoke growthbook_api_read with:
Check the returned key, project, value type, default value, disabled state of every environment, and absence of unintended rules. Report those facts rather than “success.” No targeting or exposure change is included in this example.
Choose the route that fits the runtime
Once the procedure and API operation are shared, the remaining choice is operational. Where does the agent run? What can it execute? How does it authenticate? What does your team need to inspect afterward?
Shell access favors terminal composition
A shell-capable agent can run the CLI alongside repository tools, save structured output, and combine product inspection with local checks. That is useful when the job includes code changes, generated files, or a reproducible script.
For example, a flag audit can produce an inventory file while an engineer separately checks code references. The agent should preserve the association between the GrowthBook key and each repository reference. The final artifact can include both the product state and the proposed code diff.
The shell makes composition available; it doesn't make a workflow safe by default. A script can select the wrong profile or swallow an error. Decide which failures stop the workflow, where outputs are stored, and which steps need a reviewable artifact.
Remote tool access favors MCP clients
MCP is useful when the host already provides a tool connection but doesn't expose a terminal. A PM can inspect an experiment through a compatible assistant without installing a product CLI inside that assistant's runtime.
The MCP authorization specification defines an authorization framework for HTTP transports. GrowthBook Cloud uses browser OAuth, while local stdio configurations use credentials supplied to the process. Those are distinct deployment paths.
MCP also gives hosts a structured description of tools. The tool specification includes annotations such as read-only and destructive hints. Hosts can use those signals in their interaction design, but the signals are not an access-control boundary. The product must still enforce the caller's actual permissions.
Use a small decision table
| Your immediate requirement | Route to consider | What to verify |
|---|---|---|
| Combine product operations with local files and scripts | CLI plus maintained skills | Shell access, profile, installed version, structured output |
| Connect a compatible assistant without a shell | Hosted MCP | HTTP/OAuth support, identity, tools, bundled workflow |
| Keep requests inside a self-hosted deployment | CLI or self-hosted MCP | Network reachability, server version, credentials, trusted app origin |
| Reuse a procedure across different team clients | Shared skills through either route | Workflow revision, API compatibility, expected review artifact |
You can support more than one row. An engineer's CLI and a PM's MCP connection can operate on the same objects with different identities and permissions. Standardizing the workflow is often more useful than standardizing everyone's client.
Compare actual outcomes, not tool counts
Four MCP tools can address a large API. A large CLI command catalog can expose the same operations. Counting entries tells you little about whether an agent completed the intended job correctly.
Likewise, there is no universal token or speed result implied by the architecture. The client, model, instructions, response size, pagination, and number of requests all affect a real run. Measure the work you need instead of importing a result from an unrelated integration.
Keep the evaluation task constant
Use one sandbox project and one bounded task. For a read test, ask each route to find a named flag and identify its enabled environments, current revision, and relevant dependencies. For a write test, use separate temporary keys with the same reviewed disabled-flag requirements.
Give both runs the same expected output. Record whether each identified the correct objects, loaded the relevant workflow, handled missing data, and preserved the boundary between creation and exposure. Measure elapsed time and context consumption only alongside those correctness checks.
If one run gets rich workflow guidance and the other gets only a command name, you're testing the guidance as well as the interface. That can still be a useful product evaluation, but describe what changed.
Test failure behavior deliberately
Try a nonexistent object, an existing key, and a credential without the required permission. The agent should identify the failure and stop the dependent action. It should not invent an ID, silently pick another environment, or reinterpret a permission error as permission to retry with a broader credential.
The revision workflow adds another important test: multiple open drafts. When a chain of changes belongs in one revision, the agent must preserve its version rather than repeatedly ask for whichever draft is latest.
A creation receipt and a publication receipt are different artifacts. If your evaluation only checks that a request returned without error, it can miss the point where a proposed change became live or where a draft failed to include the intended edits.
Record the versions behind the result
Capture the CLI version, server version when available, client configuration, and the skill text or revision used. With MCP, inspect the guidance actually returned by the connected server. With installed skills, inspect the local instructions actually loaded.
That record makes a later regression diagnosable. A changed result may come from new guidance, a client update, a changed API, or different product state. “MCP became worse” is too broad to help you fix it.
Build workflows that survive the next client
The most useful consequence of GrowthBook's design is organizational. Engineers, PMs, and analysts can choose the agent surface that fits their work while referring to the same flags, experiments, and metrics.
An engineer can prepare a disabled flag from a terminal. A reviewer can inspect its draft in the app. An assistant connected through MCP can retrieve the same object and explain its state. The handoff should carry an ID, a revision where applicable, the proposed behavior, and the decision still required.
This is where the CLI-versus-MCP question loses much of its importance. Your release procedure doesn't need to be rewritten around each client. The product holds state; the API exposes operations; skills explain the work; the chosen interface delivers access.
Start with one inspection or sandbox creation. Require the agent to return a concrete object and its verified state. Then add the next workflow only when the current one is reliable enough for your team to review.
GrowthBook's feature flag platform gives that work a common place to live. The durable choice is how you connect release control and measurement to your team's process. CLI and MCP are ways to carry that process into the tools people already use.
Start with a common foundation
Set up GrowthBook for the flags, experiments, and metrics your agents will share. Then choose the CLI or MCP connection that fits each team member's work.
Get Started With GrowthBook
Standard deviation vs variance: Key differences for A/B testers
A metric can have wide user-to-user variation and still yield a precise experiment estimate.
That is why confusing standard deviation with standard error creates bad A/B testing decisions. A dashboard may show that users differ substantially while the average effect is estimated closely enough to guide a release. Those statements can both be true.
Variance and standard deviation describe spread. Variance works on a squared scale; standard deviation takes its square root to return to the metric's original units. Neither is automatically the uncertainty around an experiment result.
For A/B testers, the useful distinction is practical: use standard deviation to communicate outcome variability, use variance in the calculations that combine uncertainty, and inspect the standard error or interval for the treatment effect. Start by making sure all three describe the correct unit of analysis.
Understand the difference in units
Variance uses squared distances
Outcomes above and below a mean have deviations with opposite signs. Simply averaging those signed deviations gives zero. Variance avoids that cancellation by squaring each deviation before combining them.
The sample variance formula is s² = Σ(xᵢ − x̄)² / (n − 1), where x̄ is the sample mean and n is the number of observations. The symbol Σ means to add the terms across observations.
If the outcome is measured in seconds, variance is measured in seconds squared. That is mathematically useful but less intuitive for explaining a product experience. “Variance is 4 seconds squared” does not mean users differ by 4 seconds.
Standard deviation returns to the original scale
Standard deviation is s = √s². A variance of 4 seconds squared corresponds to a standard deviation of 2 seconds. Both describe the same dispersion, expressed on different scales.
Do not define standard deviation as the average absolute distance from the mean. That is a different measure. Squaring deviations gives large deviations more influence, and taking the square root afterward does not undo that weighting.
| Quantity | What it describes | Units for task time |
|---|---|---|
| Variance | Squared dispersion in outcomes | Seconds squared |
| Standard deviation | Outcome dispersion on the original scale | Seconds |
| Standard error of the mean | Sampling variability of an estimated mean | Seconds |
Neither variance nor standard deviation requires a normally distributed population merely to be calculated. Normality matters for particular interpretations and inferential procedures, not for the existence of these summaries when the required moments are finite.
Calculate both from the same observations
Work through a small dataset
Use four synthetic task times: 2, 4, 4, and 6 seconds. This tiny dataset is for arithmetic, not evidence about a real product or a basis for confident inference.
The mean is (2 + 4 + 4 + 6) / 4 = 4 seconds. Deviations from the mean are −2, 0, 0, and 2 seconds. Their squares are 4, 0, 0, and 4 seconds squared, totaling 8.
Treating these observations as a sample, the usual sample variance is 8 / (4 − 1) = 8/3, or about 2.667 seconds squared. The sample standard deviation is √(8/3), or about 1.633 seconds.
This is a useful check on a report. If someone describes the same sample's variance as 1.633, they have probably substituted the standard deviation. If the units are missing, the mistake is much harder to spot.
Choose sample or population formulas deliberately
If those four observations constitute the entire finite population you want to describe, population variance divides by 4: 8/4 = 2 seconds squared. Population standard deviation is √2, or about 1.414 seconds.
The population and sample distinction depends on what you are estimating. Having every recorded event from an experiment does not necessarily make those events the full population of future users or future conditions you care about.
The n − 1 denominator makes the usual sample variance an unbiased estimator of population variance under independent, identically distributed sampling with finite variance. It does not make the square root exactly unbiased for population standard deviation. Nor does it correct biased sampling or dependence between observations.
Verify the calculation with explicit function names
Python's statistics functions distinguish sample calculations from population calculations. With Python 3 installed, this standalone example requires no external packages or data:
The first line of output is 2.667 1.633; the second is 2 1.414. The different denominators explain the difference. Before comparing statistics from two tools, check their sample/population defaults and handling of missing values.
Find the noise you can reduce
Explore practical variance reduction methods, including metric design and CUPED, and the conditions that make each approach useful.
Read the Variance Reduction Guide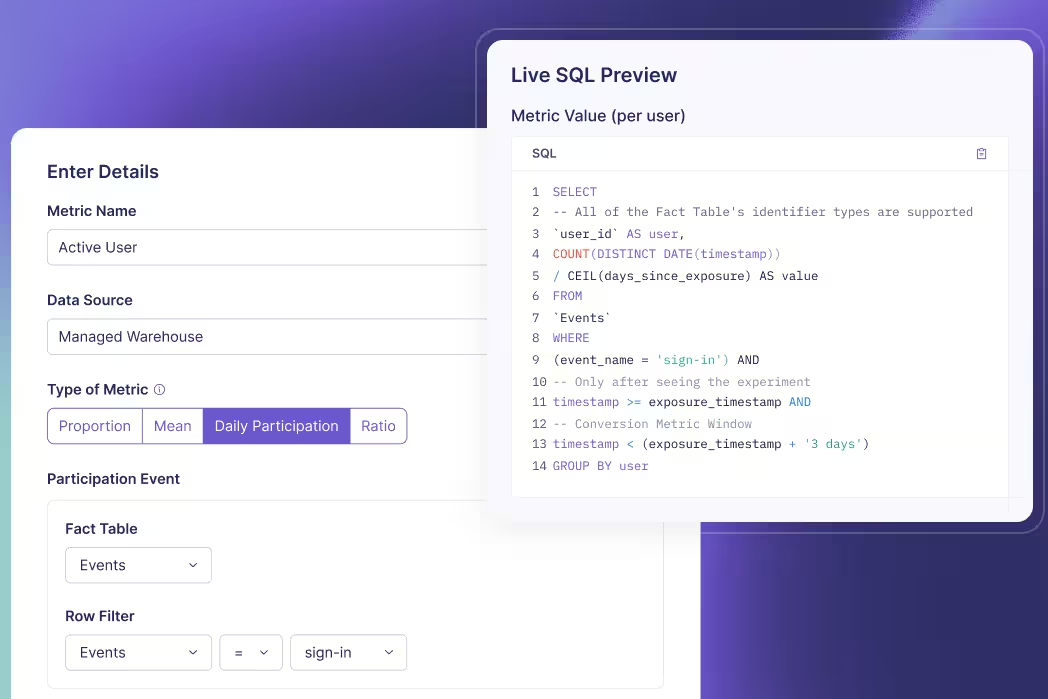
Use standard errors for experiment uncertainty
Distinguish users from estimated means
Standard deviation describes how users' outcomes vary. Standard error describes how an estimator would vary across repeated samples. For an independent sample, the estimated standard error of its mean is s / √n.
Suppose a user-level task-time metric has a sample standard deviation of 20 seconds among 10,000 independent users. The estimated standard error of the mean is 20/√10,000 = 0.2 seconds. Large differences between users coexist with a much smaller uncertainty around their average.
Collecting four times as many independent users would halve this standard error if the outcome variance stayed similar. It would not mechanically halve user-level standard deviation. The individual experience remains variable even as the estimated mean becomes more precise.
Combine arm variances before taking the square root
For independent treatment and control groups, a simple unadjusted difference in means has estimated variance s²ₜ/nₜ + s²꜀/n꜀. Its standard error is the square root of that sum. You do not add the two arm standard deviations and call the result the experiment's uncertainty.
Take a separate synthetic summary with 10,000 independent users in each arm and a 20-second standard deviation in both. The variance of the estimated difference is 400/10,000 + 400/10,000 = 0.08 seconds squared. Its standard error is √0.08, about 0.283 seconds.
If the observed treatment-minus-control difference is −1 second, an illustrative large-sample, unadjusted 95% normal interval is −1 ± 1.96 × 0.283, approximately −1.554 to −0.446 seconds. Negative values mean faster completion under this metric definition.
This example assumes independent groups and an appropriate large-sample approximation. It is not the exact output of GrowthBook's relative-lift, sequential, covariate-adjusted, or ratio-metric methods. GrowthBook's statistical details describe how the platform estimates effects and their uncertainty.
Avoid interpreting intervals as outcome ranges
That interval concerns the mean treatment effect. It does not say that 95% of individual users improved by between 0.446 and 1.554 seconds. An individual user's causal effect is a different quantity, and the experiment does not observe both potential outcomes for the same person.
Likewise, mean ± one standard deviation is not a universal statement about where 68% of users fall. That familiar interpretation depends on an approximately normal distribution. Skewed task times or revenue can look very different.
The frequentist confidence level describes the repeated-sampling coverage of the interval procedure under its assumptions. It is not a posterior probability assigned to a fixed realized interval.
Check what your metric actually measures
Match the variance to the randomization unit
If users are randomized and each contributes many requests, request rows are not automatically independent experimental units. Treating 100 requests from one person as 100 unrelated users can make uncertainty look smaller than it should.
Define the outcome at the intended unit or use a method that accounts for clustering. GrowthBook's aggregate data requirements are relevant when supplying precomputed summaries: the sample size, sum, and dispersion must correspond to the statistic and analysis method.
Two teams can report different standard deviations without either making an arithmetic mistake. One may summarize per-request latency while the other summarizes each user's average latency. They are describing different outcome distributions. Clarify the grain before comparing their numbers.
Paired measurements need another distinction. If the same users provide before-and-after outcomes, the measurements within each pair can be correlated. Analyze each user's difference or use an appropriate paired method; do not apply the independent-arm formula automatically. The paired-means framework treats those differences as the observations of interest. Pairing also does not remove time trends or establish causality by itself; the design still determines which comparison is defensible.
Inspect tails instead of deleting them casually
Large observations influence both variance and standard deviation. A few unusually long tasks can dominate a time metric; a few large purchasers can dominate revenue. Determine whether those values reflect valid behavior, instrumentation defects, retries, or unit errors.
A valid expensive user is not automatically an outlier to discard. Removing high values after seeing an experiment result can change the estimand and introduce selective analysis. Decide justified exclusions or transformations before interpreting the test.
Report complementary summaries when they answer useful questions: a histogram, median, or a relevant tail percentile can show what a single spread measure hides. Those summaries do not replace the mean effect if the mean remains the decision metric.
Keep units consistent across pipelines
Converting seconds to milliseconds multiplies every value by 1,000. Standard deviation also multiplies by 1,000, but variance multiplies by 1,000,000. A dramatic numerical variance increase can therefore be a unit conversion rather than a product regression.
For the four-value example, sample standard deviation becomes approximately 1,633 milliseconds and variance becomes approximately 2,666,667 milliseconds squared. The underlying task times have not changed. Store units with metric definitions and inspect them when comparing dashboards.
A lower variance caused solely by rescaling a metric does not create more statistical information. The effect size rescales too. Separate a numerical change in units from an actual improvement in the precision of your estimate.
Also avoid averaging standard deviations from daily reports and labeling the result a weekly standard deviation. The complete-period spread depends on both variation within days and differences between daily means. Keep the underlying observations or sufficient summaries that support the intended calculation. A simple average of displayed daily values generally loses information needed to reconstruct the full distribution.
Turn spread into a better testing plan
Define the outcome before planning the sample
Start with the metric definition: population, identity, aggregation, window, units, exclusions, and desired effect. Estimate variability from representative historical data at that same grain.
Historical variance is an input, not a guarantee. New traffic, a different user mix, or a changed measurement window can alter it. Explore plausible variance and effect-size assumptions rather than treating one historical number as exact.
Keep the two arm variances separate when appropriate. A treatment can change variability as well as its mean. The simple equal-standard-deviation illustration above is a teaching assumption, not a requirement that production groups have identical spread.
Reduce estimation noise without hiding behavior
CUPED and post-stratification use suitable pre-experiment information and covariates to improve effect estimation. CUPED stands for Controlled-experiment Using Pre-Experiment Data. Its value depends on useful predictive information and a valid implementation.
Adjustment can reduce uncertainty in the treatment effect without making real users' outcomes less variable. That distinction prevents a reporting error: a narrower adjusted interval is not evidence that customers now experience a more consistent product.
Also separate missing data from genuine zeros. A user with no purchase may correctly contribute zero revenue; a missing instrumentation event might represent an unknown outcome. Treating both identically can distort the mean and its variance before any statistical engine sees the data.
Report the right quantity for the decision
| Reader's question | Useful quantity |
|---|---|
| How much do individual outcomes differ? | Standard deviation, with distribution context |
| What enters this uncertainty calculation? | Variance at the correct analysis unit |
| How precisely is the effect estimated? | Standard error and an appropriate interval |
| Is the measured difference worth acting on? | Effect size, uncertainty, guardrails, and decision context |
For a clear experiment readout, show the metric's unit and analysis grain, the estimated effect, and its appropriate uncertainty interval. Add outcome spread when it helps readers understand the population or diagnose a noisy metric.
GrowthBook's experimentation platform brings defined metrics and statistical analysis together. A trustworthy interpretation still starts with your measurement choices: describe spread with standard deviation, calculate with variance where required, and judge precision using the estimator's uncertainty.
Build a clearer experiment readout
Connect your metrics to GrowthBook and evaluate effects with the analysis method and measurement definitions your team has chosen.
Get Started With Experimentation
Catching 80 defects means little until you know how many defects existed.
Suppose a detector flags 125 suspicious software changes. Engineers inspect them and confirm 80 real defects. That tells you something about alert quality, but it does not tell you how many defects the detector missed. To calculate true positive rate, you need the actual positives outside the alert queue too.
True positive rate, or TPR, measures the share of actual positive cases that a system correctly identifies. It is also called recall or sensitivity. The formula is TP / (TP + FN), where TP means true positives and FN means false negatives.
The arithmetic is simple. Choosing the right population, labels, threshold, and denominator is the difficult part. This guide works through an engineering example, distinguishes neighboring metrics, and explains what changes when the “test” is an A/B experiment rather than an item classifier.
Start with actual positives, not alerts
Define the positive class
“Positive” means the condition you want to detect. It does not necessarily mean a good outcome. In a defect detector, positive means a real defect. In a spam filter, it means spam. Write that definition before calculating anything.
A true positive is an item that is actually positive and predicted positive. A false negative is actually positive but predicted negative. Those two groups together form the denominator: all actual positives in the evaluation sample.
The recall definition is therefore conditional on actual class membership. TPR asks, “Among the real defects, what proportion did we catch?” It does not ask, “Among the alerts, what proportion were real?”
Fix the unit and observation window
Choose a consistent evaluation unit. A code change, an individual finding, and a repository are different units. If one change generates 12 duplicate alerts, counting alerts in the numerator and changes in the denominator produces a meaningless rate.
For the example, each unit is one code change, evaluated once by one fixed detector version at one fixed threshold. An independent review process eventually labels each change as defective or not defective. The observation window is long enough for those labels to mature.
This resembles the discipline needed when defining experiment metrics: the event, identity, time window, and denominator must describe the same question. A correct formula applied to incompatible counts still gives the wrong answer.
Calculate TPR from the confusion matrix
Put every evaluated item in one cell
Consider an original synthetic evaluation of 1,000 code changes. Reviewers establish that 100 contain a defect and 900 do not. The detector catches 80 defects, misses 20, and incorrectly flags 45 nondefective changes.
| Actual label | Predicted positive | Predicted negative | Total |
|---|---|---|---|
| Defective | 80 true positives | 20 false negatives | 100 |
| Not defective | 45 false positives | 855 true negatives | 900 |
| Total | 125 | 875 | 1,000 |
Read the labels rather than relying on cell position. Libraries and reports can arrange axes differently. The scikit-learn confusion matrix convention uses actual classes on rows and predicted classes on columns, with class order also affecting where each value appears.
Check the totals before calculating rates. The four cells sum to 1,000. True positives plus false negatives sum to 100 actual defects. Predicted positives total 125, which is a different denominator.
Divide detected positives by all actual positives
The calculation is:
TPR = TP / (TP + FN) = 80 / (80 + 20) = 80 / 100 = 0.80 = 80%.
Interpret it in words: the detector caught 80% of the actual defects in this evaluation sample. It missed 20%, so the false negative rate is 20%. For a binary task with complete labels, TPR and false negative rate sum to 100%.
Do not divide 80 by 1,000. That would measure true positives as a share of all evaluated changes, not recall. Do not divide 80 by 125 either. That is precision, which answers the alert-quality question.
The result describes this sample and threshold. It does not establish that every future workload will have the same recall, or that all defect categories are equally detectable. Keep the counts beside the percentage so readers can see the support behind it.
Handle zero positive support explicitly
If the sample contains no actual defects, TP + FN equals zero. Sample TPR is undefined. Returning 0% would imply the detector missed known defects; returning 100% would imply it successfully found them. Neither interpretation is supported.
Software libraries need a practical zero-division convention. That convention can return a placeholder or warning, but it does not create evidence. Report “TPR unavailable: zero actual positives” and preserve the support count. A pipeline can then distinguish an unevaluable slice from measured poor performance.
Check the experiment error risks
See how power, repeated checks, and multiple comparisons affect the reliability of experimental decisions beyond a single classifier score.
Read the False Positives GuideCompare TPR with precision and false positives
Keep the denominators visible
For the same 1,000 changes, the other common metrics tell different stories:
| Metric | Calculation | Result |
|---|---|---|
| True positive rate / recall | 80 / 100 actual positives | 80% |
| Precision | 80 / 125 predicted positives | 64% |
| False positive rate | 45 / 900 actual negatives | 5% |
| Specificity | 855 / 900 actual negatives | 95% |
| Accuracy | (80 + 855) / 1,000 changes | 93.5% |
The classification metric definitions differ because they condition on different populations. Here, 36% of alerts are false, but the false positive rate is 5%. Calling both numbers “the false positive rate” hides the operational distinction.
Accuracy can also look reassuring in an imbalanced population. A detector that labels all 1,000 changes nondefective would be 90% accurate while detecting none of the 100 defects. TPR exposes that failure, though it still needs the false-positive side of the picture.
Choose a threshold for the decision
Suppose a stricter threshold, evaluated on the same labeled changes, catches 60 defects and incorrectly flags 10 nondefective changes. Its TPR is 60%, its precision is about 85.7%, and its false positive rate is about 1.11%.
This threshold reduces the review queue from 125 changes to 70. It also misses 40 defects instead of 20. Whether that tradeoff is acceptable depends on the consequences of a missed defect, the review team's capacity, and what action follows an alert.
A ROC curve plots TPR against false positive rate across thresholds. It helps compare operating points. It does not pick the operational threshold for you, and an area-under-curve summary does not specify the queue size at the threshold you intend to deploy.
If you tune thresholds using the same labels you later report as a final evaluation, the score can be optimistic. Use separate validation and held-out evaluation data, or another defensible evaluation design, and freeze the decision rule before the final assessment.
Specify the action at each threshold too. A low-confidence finding might create a suggestion, while a high-confidence finding might block a merge. Those are different interventions with different error costs. One aggregate recall figure should not imply that every detected item received the same treatment.
Make sure the labels can support the claim
Audit predicted negatives too
If engineers review only alerts, you can estimate precision within the reviewed alert population. You cannot directly count missed defects among unreviewed negatives. Assuming those changes are clean makes FN artificially small and TPR artificially high.
An evaluation may need independent review of a representative sample of predicted negatives, delayed incident labels, or a curated benchmark with known defects. Each approach has limits. Incident labels miss undetected failures; curated examples can differ from ordinary production work.
If the evaluation oversamples suspicious changes or certain repositories, report that design. Use appropriate weighting when estimating performance for the real workload. A simple unweighted confusion matrix describes the sampled dataset, which may not represent the deployed population.
Preserve uncertainty and segment support
An 80% estimate based on 4 detected defects out of 5 is much less precise than one based on 800 out of 1,000. The important sample size for recall is the count of actual positives, not just the total number of changes evaluated.
Report positive support by important slices, such as language, defect category, or repository type. A high pooled TPR can hide weak performance on a rare but expensive failure mode. At the same time, avoid declaring tiny slices definitively better or worse from a few examples.
Counts alone do not make observations independent. Many similar changes from one repository can share a common pattern. Use uncertainty methods that fit the evaluation design rather than assuming every row is an unrelated trial.
Separate label delay from label absence
A recently deployed change might appear nondefective because nobody has had time to find the bug. Treating it as a confirmed negative gives the newest cohort a different labeling standard from older cohorts.
Define when an item becomes eligible for evaluation and track unresolved labels separately. Keep model version, threshold, label version, and observation dates with the result. That makes a later score change interpretable: you can tell whether the detector changed, the workload changed, or the labels matured.
For a warehouse-native measurement workflow, these definitions belong in the underlying data model. Joining model decisions to review outcomes still requires identity and time alignment; a queryable warehouse does not automatically resolve ambiguous ground truth.
Keep comparable populations together
When comparing detector versions, evaluate them on the same held-out cases where possible. Otherwise, an apparent recall improvement could come from an easier mix of defects. Preserve a breakdown of new, removed, and unchanged cases so reviewers can see what changed between evaluations.
When combining reports, add the underlying TP and FN counts for nonoverlapping, consistently defined populations, then calculate the pooled rate. An unweighted average of repository percentages answers a different question because it gives a tiny repository the same influence as a large one. Either summary can be useful, but label the weighting explicitly.
If the same change appears in several reports, deduplicate or model that repeated observation before pooling. Repeated scans do not create additional independent defects. Keep an audit trail from the final counts back to the evaluated item identifiers so a suspicious rate can be investigated.
Connect detection quality to product decisions
Distinguish classifier recall from statistical power
In hypothesis testing, statistical power is the probability that a testing procedure rejects the null when a specified alternative is true. It is a repeated-test detection probability, depending on assumptions such as effect size, variance, sample size, and decision rule.
That is related to the idea of detecting a real signal, but it is not the same dataset as a labeled-item confusion matrix. In an ordinary A/B program, you do not observe the true causal effect of every experiment with certainty. Dividing declared winners by all experiments does not reveal a ground-truth TPR.
Power planning asks how often your procedure would detect a particular real effect under its assumptions. A classifier evaluation asks how many labeled positives were detected in the evaluated sample. Keep those questions separate when discussing GrowthBook's statistical methods.
Evaluate the intervention as well as the detector
An improved offline detector can still create a worse product workflow. More alerts might overwhelm engineers, delay releases, or catch defects too late to matter. Conversely, a modest recall change might be valuable if it catches the failures with the highest operational cost.
When appropriate, use randomized experiments to evaluate the downstream intervention: which review experience helps teams resolve defects, with what delay and cost? Keep detector recall, review workload, and product outcomes as separate measures.
GrowthBook's experimentation platform can analyze defined outcomes from such tests. Your team supplies reliable assignment, exposure, labels, and metric definitions. Neither a high TPR nor a significant product result eliminates the need to inspect the other evidence.
Use a repeatable reporting checklist
Before sharing a TPR number, state the positive class, evaluation unit, detector version, threshold, and label process. Show TP and FN beside the rate. Include precision or false positive rate so readers can assess the workload created by detection.
Then ask whether predicted negatives were evaluated, whether labels had time to mature, and whether the sample reflects the population where you will act. Mark zero-support slices unavailable and explain material gaps in coverage.
The useful result is a statement someone can audit: “At this threshold, the detector found 80 of 100 labeled defects in these 1,000 evaluated changes, while producing 45 false alerts.” That is a clearer basis for a decision than “our model is 80% accurate.”
Measure what the change delivers
Connect your data and defined metrics to GrowthBook to evaluate how a product or workflow change affects the outcomes your team cares about.
Start Measuring With GrowthBookReady to ship faster?
No credit card required. Start with feature flags, experimentation, and product analytics—free.