Why GrowthBook is better than LaunchDarkly for enterprise customers

Enterprise feature flag platforms fail in two ways: they become too expensive to use broadly, or they become too disconnected from the metrics that decide whether a release worked.
That is why the GrowthBook vs LaunchDarkly decision is not only a feature checklist. LaunchDarkly is a mature feature management platform. It is strong at enterprise rollout control, targeting, approvals, and release workflows. If your main problem is coordinating many engineering teams around production releases, LaunchDarkly deserves a serious look.
But most enterprise product teams are not buying feature flags only to flip features on and off. They want to ship safely, measure impact, reuse trusted metrics, control vendor costs, satisfy security reviews, and make experimentation part of normal product development.
That is where GrowthBook is better than LaunchDarkly for many enterprise customers. GrowthBook combines feature flags, experimentation, product analytics, warehouse-native metrics, and flexible deployment in a way that fits how product, engineering, and data teams actually work together.
This article breaks down the comparison across the enterprise criteria that matter: pricing, experimentation depth, data architecture, deployment control, governance, reliability, and migration risk.
The short answer: GrowthBook is better when measurement matters as much as rollout control
LaunchDarkly is strongest when feature management is the main job. GrowthBook is stronger when feature management needs to connect directly to experimentation, trusted metrics, data ownership, and cost control.
That distinction matters more as an organization grows. A small team can manage feature flags as a developer convenience. An enterprise has to manage them as production infrastructure. The platform affects engineering workflow, data governance, procurement, security review, and how product teams decide whether a release should keep rolling out.
| Enterprise decision criterion | GrowthBook | LaunchDarkly |
|---|---|---|
| Best center of gravity | Feature flags, A/B testing, product analytics, and warehouse-native metrics in one platform | Feature management, release workflows, targeting, and enterprise rollout control |
| Pricing shape | Seat-based cloud pricing, free cloud tier, Enterprise, and self-hosted open-source options | Developer tier, usage-priced Foundation, custom Enterprise and Guardian packaging |
| Data model | Queries your warehouse and exposes SQL for experiment analysis | Offers experimentation and warehouse-native metrics, but the broader platform is SaaS-first |
| Deployment control | GrowthBook Cloud or Self-hosted GrowthBook, including air-gapped options | Managed cloud service, with enterprise infrastructure options but no full self-hosted product |
| Experimentation fit | Experimentation is a core workflow tied to flags and metrics | Experimentation exists, but the platform is feature-management-first |
| Enterprise strength | Cost control, data control, self-hosting, transparent analysis, unified product-development workflow | Mature release governance, approvals, targeting, SDK breadth, and release monitoring |
This does not make LaunchDarkly weak. It makes the evaluation sharper.
Choose LaunchDarkly if the company primarily needs a centralized release control plane with mature enterprise workflows.
Choose GrowthBook if the company wants feature flags to become the operating layer for experimentation, product analytics, and measurable product development.
Pricing becomes an architecture question at enterprise scale
Enterprise pricing problems rarely show up during a pilot. They show up after the platform becomes standard.
The first few flags are easy to justify. The bill becomes harder to forecast when every service, environment, frontend surface, mobile app, experiment, and release workflow starts depending on the platform. That is why pricing model matters as much as sticker price.
LaunchDarkly pricing has several usage dimensions
LaunchDarkly's current pricing page has a free Developer tier, a usage-priced Foundation tier, and custom Enterprise and Guardian tiers. Foundation pricing includes service connections and client-side monthly active users. The comparison table also introduces other dimensions such as experimentation usage, observability usage, replays, errors, traces, logs, data export, and higher-tier governance features.
That shape can make sense for some teams. A platform engineering organization with stable service counts and clear release governance needs may find the model workable.
The challenge is forecasting. LaunchDarkly's service connections documentation defines a service connection as one server-side SDK instance connected to one LaunchDarkly environment for a measured period. In practice, applications, replicas, environments, and SDK instances can all affect the count. A company that thinks in terms of "apps" can be surprised when billing follows the actual runtime topology.
Client-side usage adds another variable. If browser, mobile, or desktop users encounter flags directly, pricing can move with product adoption. Experimentation, observability, and data export can add more planning questions.
None of this means LaunchDarkly is overpriced for every enterprise. It means the pricing model needs a real architecture review before standardization.
GrowthBook pricing is easier to model for high-scale product teams
GrowthBook's pricing page is built around a different idea: charge for the internal users who manage flags, experiments, and analytics, not for every end user who encounters a flag.
That is especially useful for enterprise teams where product traffic grows faster than the number of people operating the platform. A high-traffic product can run many feature flags and experiments without treating end-user exposure as the primary cost driver.
GrowthBook also gives teams more deployment choices. GrowthBook Cloud and Self-hosted GrowthBook use the same core platform, and the self-hosted path includes open-source and enterprise options. That gives procurement and security teams more ways to match the platform to internal requirements.
The practical enterprise question is not "which tool is always cheaper?" It is "which pricing model still makes sense when every team starts using the platform?"
For many enterprise teams, GrowthBook wins because the cost model is easier to explain to engineering, finance, and data leaders.
Experimentation should not be an add-on to release control
Feature flags answer one question: who sees this code?
Experimentation answers a different question: did this code improve the product?
Enterprise teams need both. If those workflows live too far apart, releases become visible but not measurable. Product teams ship behind flags, but the decision to roll forward still depends on dashboards, analyst tickets, manual exports, or disconnected metric definitions.
LaunchDarkly has experimentation, but its center of gravity is feature management
LaunchDarkly supports experimentation. Its experimentation documentation covers running experiments, analyzing results, Bayesian and frequentist analysis, multi-armed bandits, holdouts, and warehouse-backed metrics. Its experiment flags documentation describes temporary flags that test a hypothesis and pair variations with metrics.
That is a credible experimentation surface. LaunchDarkly is not a "flags only" tool anymore.
The question is where the product is optimized. LaunchDarkly is organized around feature management first: flags, targeting, release workflows, approvals, monitoring, and governance. Experimentation sits alongside that release-control model.
That may be fine for teams where experimentation is occasional. It is less ideal for companies where experiments are the operating model for product development.
GrowthBook treats experimentation as the primary measurement loop
GrowthBook is built around the idea that every meaningful product change can be shipped safely and measured rigorously.
Feature flag experiments in GrowthBook use experiment rules to assign variations, target specific users, track exposure through your event pipeline, and analyze results against metrics in your data warehouse. The same flag can support rollout control and measurement, so the product team is not bolting an experiment workflow onto a separate release tool.
That matters for enterprise adoption. Engineers care about safe rollout. Product managers care about decision quality. Data teams care about metric definitions, assignment data, sample ratio mismatch, statistical methods, and whether results can be audited. GrowthBook brings those groups into one workflow.
GrowthBook's experimentation platform also supports the practices mature teams need: A/B tests, feature-flag experiments, holdouts, sequential testing, Bayesian and frequentist workflows, variance reduction, metric libraries, and decision frameworks.
For an enterprise that wants to make experimentation normal, not occasional, GrowthBook is usually the better fit.
Warehouse-native metrics make experiment results easier to trust
Enterprise teams already have metric definitions. They live in the data warehouse, BI layer, semantic layer, dbt models, notebooks, dashboards, or a mix of all of those. A feature flag platform becomes more useful when it can work with those definitions instead of asking teams to rebuild them in a vendor system.
This is one of GrowthBook's clearest advantages.
GrowthBook uses the warehouse as the measurement source of truth
GrowthBook's warehouse-native architecture is designed around the data enterprises already trust. GrowthBook queries data where it lives, exposes visible SQL, and lets teams define metrics in a way that matches their business logic.
The data source configuration docs explain the mechanics. GrowthBook connects to your data warehouse, defines assignment queries and metric queries, and uses SQL templates to generate experiment results. It works with common event sources and custom schemas, which matters because enterprise data rarely fits a vendor's perfect example.
This has three practical benefits:
- Data teams can inspect and reproduce the SQL behind an experiment result.
- Product teams can use metrics the company already trusts.
- Engineering teams can connect feature rollout to measurable impact without building a separate analytics pipeline for every release.
GrowthBook's statistics docs reinforce the same point: experiment analysis should be understandable, inspectable, and connected to the data the organization already uses.
LaunchDarkly has warehouse-native metrics, but not the same platform model
LaunchDarkly has moved toward warehouse-backed experimentation. Its documentation includes warehouse-native metrics, external warehouse setup, and warehouse-backed experiment workflows.
That is important, and it is a real strength compared with older feature flag tools.
The difference is architectural emphasis. GrowthBook is warehouse-native by design. LaunchDarkly is a SaaS feature management platform that has added warehouse-native measurement capabilities for experimentation.
For enterprises where the data warehouse is the source of truth, that distinction affects more than analytics. It affects security review, metric governance, debugging, cost control, and how quickly data teams trust experiment results.
If the buyer is a platform engineering team, LaunchDarkly's release control may matter most. If the buyer includes data science, analytics, product, and growth leadership, GrowthBook's warehouse-native model is usually the stronger enterprise argument.
Deployment control is a real enterprise requirement
Some enterprises can use any managed SaaS product after a standard security review. Others cannot.
Healthtech, fintech, edtech, AI infrastructure, public sector-adjacent software, and large B2B platforms may need stricter control over data residency, access boundaries, infrastructure, and compliance posture. For those teams, deployment options are not a nice-to-have.
GrowthBook supports cloud, self-hosted, and air-gapped deployment paths
GrowthBook deployment options include GrowthBook Cloud and Self-hosted GrowthBook. The self-hosted path gives teams control over updates, scaling, infrastructure, data boundaries, and deployment topology. GrowthBook's security page also describes self-hosted and air-gapped options for teams that require infrastructure control.
That changes the enterprise conversation. Security teams can evaluate GrowthBook as software that can run inside the organization's own infrastructure, not only as a vendor-managed control plane.
Self-hosting is not free. Someone has to operate the system, manage upgrades, monitor uptime, and own incident response. But for enterprises with strict data requirements, that operating cost may be easier to justify than sending more production control and experiment metadata through a third-party SaaS platform.
LaunchDarkly is strong SaaS infrastructure, but not self-hosted-first
LaunchDarkly is a mature managed platform. That is a strength for many enterprise buyers. Teams get a hosted control plane, broad SDK coverage, release workflows, and vendor-managed infrastructure.
But it is not the same as full self-hosting. If the requirement is "run the platform inside our network," GrowthBook has a clearer answer.
This is not only about security posture. It is also about long-term control. Enterprises that want to inspect code, manage deployment, avoid vendor lock-in, and keep measurement close to their own data infrastructure should include self-hosting in the evaluation.
GrowthBook is better when deployment control is part of the buying criteria.
Feature flag governance still matters
The case for GrowthBook should not pretend that feature flag governance is simple.
Feature flags are production controls. A targeting rule can expose a half-finished feature. A configuration value can change business logic. A stale flag can leave dead code in a critical path. A rollback can disable a user workflow. Enterprises need permissions, audit trails, approval workflows, ownership, naming conventions, cleanup habits, and emergency procedures.
LaunchDarkly deserves credit for enterprise release governance
LaunchDarkly has invested deeply in release governance. Its approvals documentation describes approval requests for changes to feature flags, AgentControl configs, experiments, and segments. Its pricing page shows higher-tier governance features such as SSO/SAML, SCIM, audit logging, custom roles, approvals, and security and compliance packaging.
LaunchDarkly also has guarded rollouts, code references, feature monitoring, release pipelines, and workflow tooling. For platform teams standardizing release practices across many engineering groups, this is meaningful.
If an enterprise's main pain is release governance, LaunchDarkly may be the safer incumbent choice.
GrowthBook gives governance a measurement layer
GrowthBook's advantage is not that governance disappears. It is that governance connects to experimentation and product impact.
GrowthBook feature flags support targeted rollouts, percentage rollouts, instant kill switches, remote configuration, scheduled flags, approval workflows, audit history, and stale flag management. The same platform also connects flags to experiments and metrics.
That pairing matters. A release approval answers "is this change allowed to go live?" An experiment readout answers "did this change improve the product?" Mature organizations need both.
GrowthBook is especially strong when governance needs to include data teams and product teams, not only engineering and release management.
Reliability depends on evaluation model, not only vendor uptime
Enterprise buyers often ask for uptime numbers. They should. But feature flag reliability is not only a vendor uptime question. It is also an SDK evaluation question.
What happens if the control plane is slow? What value does the SDK return when configuration is stale? Does flag evaluation require a network call on the critical path? Can the app keep serving a safe default during an incident?
GrowthBook's SDK overview is explicit about how its SDKs work: they fetch feature definitions, cache them, and evaluate features wherever the SDK runs, whether in the browser, server, or edge. That local evaluation model keeps normal flag checks close to the application.
LaunchDarkly also has mature SDK behavior and infrastructure patterns, including streaming and polling. It is not fragile by default. But LaunchDarkly's value proposition often includes a live managed control plane with streaming updates, observability, and release workflows. That can be powerful, but it also requires teams to understand how their SDKs behave under network loss, stale config, initialization delay, and fallback scenarios.
For enterprise teams, the right proof of concept should include failure testing:
- Start the app with no network access.
- Serve a request while flag configuration is stale.
- Test a missing user attribute.
- Test client-side and server-side evaluation separately.
- Verify fallback values.
- Confirm whether rollout changes require a live vendor call or a cached local rule.
- Run the same test under production-like traffic.
GrowthBook is better when teams want flag evaluation and experiment assignment to be boring, inspectable, and close to their own application and data infrastructure.
The migration should prove value before it proves coverage
Do not migrate from LaunchDarkly to GrowthBook by recreating every flag first.
That is the slowest way to learn. It also moves old flag debt into a new tool.
A better migration starts with one representative workflow that proves why GrowthBook is being considered in the first place. For most enterprise teams, that workflow should include feature rollout and measurement, not only a toggle.
| Migration step | What to test | Why it matters |
|---|---|---|
| Inventory current flags | Separate release flags, experiment flags, permission flags, kill switches, and stale flags | Avoid migrating dead code and old rollout habits |
| Pick one representative service | Choose a flag used by a real backend, frontend, or mobile path | Proves SDK integration in a real environment |
| Recreate targeting rules | Match account, user, plan, geography, or internal-user targeting | Validates rule expressiveness before broader migration |
| Add one metric | Connect the rollout to a primary metric and guardrail metric | Shows whether GrowthBook improves decision quality |
| Run a feature-flag experiment | Assign variations, log exposure, and analyze results | Tests the full flag-to-experiment loop |
| Model cost at 3x and 10x usage | Compare seats, traffic, services, experiments, and support needs | Prevents the next platform from recreating the same pricing problem |
| Define cleanup | Archive the old flag, remove old code paths after review, and record ownership | Prevents migration from becoming a flag-copying project |
This is also the point where GrowthBook's broader platform becomes visible. A team can compare LaunchDarkly and GrowthBook on rollout speed, metric trust, data-team workflow, developer experience, governance, cost model, and security review at the same time.
The best migration proof is not "we recreated a flag." It is "we shipped a change, measured it with trusted metrics, made a decision, and cleaned up the flag."
One useful exercise is to write the success criteria before anyone opens either platform. The platform should pass if a product manager can define the release audience, an engineer can implement the SDK with safe defaults, a data scientist can verify assignment and metric SQL, and finance can model the same rollout at higher traffic without changing the economic logic. That forces the evaluation to reflect real enterprise work instead of demo momentum.
It also prevents the most common migration mistake: comparing the prettiest workflow in one tool against the messiest legacy workflow in the other. If LaunchDarkly has accumulated stale flags, inconsistent naming, and unclear ownership, clean those up in the baseline. If GrowthBook is being evaluated for warehouse-native measurement, include a metric that actually matters to the business. A proof of concept only proves something when both platforms are tested against the same operating standard.
When LaunchDarkly is still the better choice
GrowthBook is not the right answer for every enterprise.
LaunchDarkly may be better when:
- The organization mainly needs enterprise release governance, not experimentation.
- Platform engineering owns the buying decision and product/data teams are secondary users.
- Release workflows, approval routing, guarded rollouts, and observability are the primary requirements.
- The company's pricing model fits LaunchDarkly's service connection, client-side MAU, and enterprise packaging.
- The organization wants a mature managed SaaS control plane and does not need self-hosting.
- Existing LaunchDarkly adoption is broad, clean, and cost-effective enough that migration risk outweighs the upside.
That last point matters. A working incumbent has value. If LaunchDarkly is already standardized, the cost is predictable, and teams trust the workflow, there may be no urgent reason to switch.
The case for GrowthBook is strongest when LaunchDarkly has become expensive, experimentation has become important, metrics are hard to trust, or security teams want more deployment control.
When GrowthBook is the better enterprise choice
GrowthBook is the better enterprise choice when the company wants feature flags to become part of a broader product-development system.
That usually means the team cares about:
- Predictable pricing as traffic, services, and experiments grow.
- Warehouse-native metrics and visible SQL.
- Experimentation as a core workflow, not an occasional add-on.
- Feature flags and experiments in the same platform.
- Product analytics connected to the same data and metrics.
- Cloud and self-hosted deployment options.
- Open-source transparency and lower vendor lock-in.
- Security review that can include self-hosting or air-gapped deployment.
- A migration path that can start with one flag and one real experiment.
GrowthBook does not win because LaunchDarkly is bad. It wins because enterprise product development has changed.
Shipping safely is no longer enough. Teams also need to know whether what they shipped worked. They need the answer in metrics the company trusts. They need costs that do not punish every extra user, service, or experiment. They need infrastructure choices that fit their security profile.
That is the GrowthBook advantage.
Build the evaluation around the work your teams actually do
The GrowthBook vs LaunchDarkly comparison should end with a proof of concept, not a deck.
Pick one real feature. Put it behind a flag. Roll it out to a targeted segment. Add one primary metric and one guardrail metric. Run it as an experiment. Ask engineering how the SDK felt. Ask product whether the decision was clear. Ask data whether the result was trustworthy. Ask finance whether the 10x usage model still works. Ask security whether the deployment model fits.
If the evaluation is only about toggles, LaunchDarkly will look strong. It should.
If the evaluation is about product development at enterprise scale, GrowthBook usually tells a better story: feature flags, experimentation, product analytics, warehouse-native metrics, open-source control, and predictable pricing in one platform.
Start with a real pilot, not a generic feature matrix. Try GrowthBook free, compare it against your current LaunchDarkly workflow, and make the decision with your own flags, your own metrics, and your own architecture.
Related Articles
In healthcare, “Can we randomize it?” is the wrong first question. Start with “Could either experience change care, rights, privacy, or access?”
A/B testing can improve digital intake, appointment access, patient education, clinician workflows, and administrative operations. It can also create unacceptable risk when teams treat a clinical or consent decision like an ordinary conversion funnel.
The difference is not the label on the method. A/B tests are randomized experiments. What matters is the treatment, purpose, affected population, data flow, and oversight required in the organization and jurisdiction. This guide provides a practical product framework, not a substitute for legal, clinical, privacy, security, or institutional review.
Draw the boundary before designing variants
Create an intake step that classifies the proposed change before anyone builds a treatment. At minimum, ask:
- Can the change alter diagnosis, treatment, triage, dosage, or clinical recommendations?
- Can it delay or discourage access to care, accommodations, or urgent help?
- Does it change informed consent, privacy choice, required disclosure, or patient cost?
- Does it use protected or sensitive health information for assignment or measurement?
- Does it include children, people in crisis, or another population requiring added protection?
- Is the purpose internal quality improvement, or is it designed to contribute to generalizable knowledge?
- Could the software function fall within medical-device or clinical decision-support oversight?
The HHS quality-improvement guidance says many activities limited to improving patient care and collecting operational data are not research under the cited human-subjects regulations. It also states that some quality-improvement activities can have a research purpose, in which case human-subject protections may apply. A product team should not make that determination informally; route it to the organization’s authorized office.
Likewise, software that influences clinical decisions is not automatically an ordinary product surface. The FDA’s January 2026 clinical decision-support guidance explains that some software functions are excluded from the device definition while other patient- or caregiver-facing functions can remain subject to digital-health policy. Clinical and regulatory owners need to classify the function before experimentation.
Start with lower-risk operational questions
The safest early program tests reversible changes where both variants meet the same clinical, accessibility, privacy, and disclosure requirements.
Appointment reminder timing
Compare 2 approved reminder schedules or message structures to reduce missed appointments. Keep required details, opt-out behavior, language support, and urgent-contact instructions constant.
Use completed appointments or timely rescheduling as the primary outcome. Track cancellations, patient contacts, message delivery, opt-outs, wrong-recipient risk, and differences across language, age, disability, or access groups. A higher click rate is not enough if no-show rates or trust worsen.
Patient portal navigation
Test whether a clearer information architecture helps people complete a high-value administrative task, such as finding results, updating insurance, or sending a non-urgent message. Preserve emergency guidance and clinical escalation paths in both variants.
Measure successful task completion and time to completion. Guard against repeated navigation, abandonment, accessibility failures, mistaken message routing, and increased call-center burden. Use usability testing before the A/B test to catch failures randomization should never expose.
Administrative form sequence
Compare a long form with a staged flow, or test the order of non-clinical fields. Do not omit information needed for safe care, billing transparency, consent, or legal compliance.
Measure accurate completion, not just submission. Track validation errors, correction rates, staff rework, abandonment, and time to appointment. If the treatment collects sensitive data, confirm necessity and access controls before launch.
Educational content layout
Test 2 ways to present the same clinician-approved information: summary-first versus stepwise, text plus illustration versus text alone, or a clear action checklist versus a dense paragraph. Keep the medical meaning, risks, contraindications, and escalation advice equivalent.
Use a comprehension or appropriate next-action metric when feasible. Page time and clicks can be misleading. Accessibility, language quality, and comprehension across health-literacy levels belong in the guardrail plan.
Review the design before launch
Use a trustworthy experiment-design session to pressure-test metrics, safety checks, and decision rules before exposing patients or clinicians.
Watch the Experiment Design Session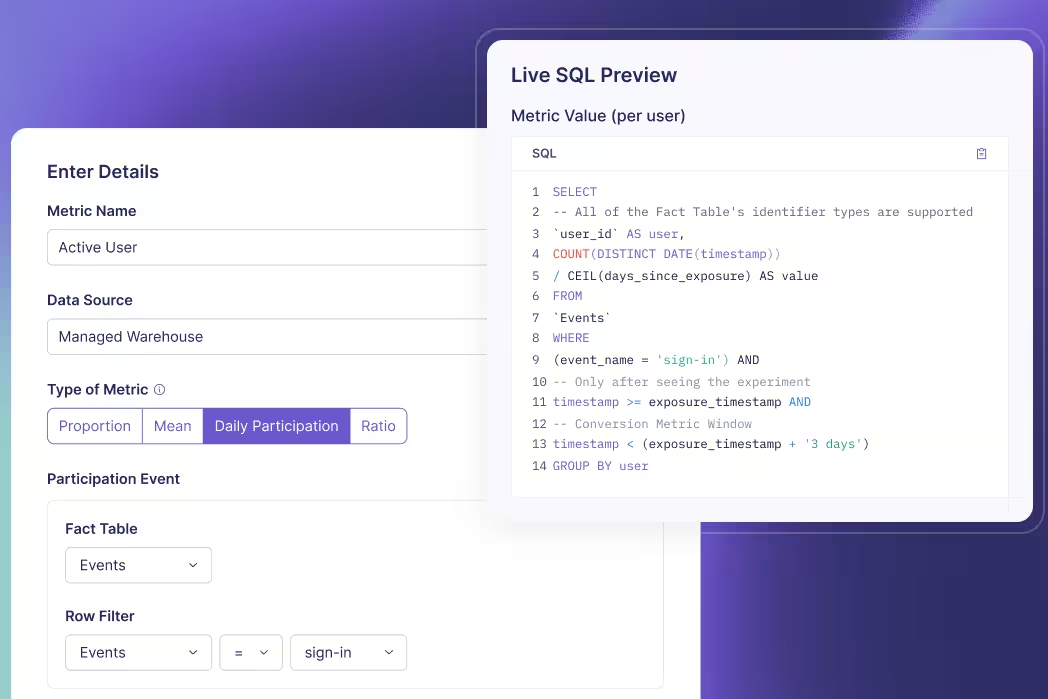
Use stronger controls for care-adjacent products
Some product changes are not clinical interventions but can still influence care. They need clinical ownership, narrower eligibility, conservative ramps, and explicit stopping criteria.
Clinician workflow support
A test might compare how a work queue prioritizes administrative follow-up, how a note template reduces documentation work, or how a non-diagnostic alert is presented. The treatment should not silently alter the clinical standard of care.
Randomize at the unit that prevents contamination. Individual clinician assignment may fail when teams share queues and handoffs; clinic- or unit-level clusters may better match the workflow. Measure task completion and time saved, with guardrails for missed work, overrides, escalations, documentation quality, and staff workload.
Preventive-care outreach
Compare approved outreach content or channels for people already eligible under the same clinical rule. Do not experiment with whether one group receives necessary care or required notice.
Use completed appropriate follow-up as the primary outcome. Track opt-outs, unreachable patients, scheduling capacity, disparities, complaints, and downstream cancellations. If the treatment drives demand beyond operational capacity, a messaging lift can make access worse.
Digital adherence support
Test the presentation or timing of an approved reminder, checklist, or educational cue. Avoid treatment changes that could be interpreted as personalized medical advice without the corresponding validation and oversight.
Measure the intended behavior with caution. Self-reported completion or app engagement is not a clinical outcome. Include adverse-event reporting, escalation pathways, disengagement, and privacy events where relevant.
Feature rollout in health software
Use feature flags to separate deployment from release, start with internal or trained cohorts, and expand only when technical and clinical guardrails remain healthy. GrowthBook’s feature flag platform supports targeted rollouts and kill switches, while the experiment layer measures impact.
The rollback plan must describe more than turning off a flag. Determine whether the old experience remains clinically and operationally safe, how queued work is reconciled, what happens to partial workflows, and who is authorized to stop exposure.
Protect data by design
Do not send a broad event stream to an experimentation vendor and decide later which fields were unnecessary. Inventory the data before implementation:
| Data question | Required decision |
|---|---|
| Assignment | What is the least identifiable stable unit that works? |
| Eligibility | Which sensitive attributes are truly needed? |
| Exposure | What event proves the treatment was delivered? |
| Outcomes | Can metrics be computed inside the governed data environment? |
| Access | Which roles can view assignments, segments, and results? |
| Retention | When are raw records, logs, and exports removed? |
The HHS minimum-necessary guidance describes limiting uses, disclosures, and requests for protected health information to what is needed for the intended purpose, with policies based on roles and recurring versus non-routine access. Apply that principle to experiment attributes, debugging logs, dashboards, and downloaded readouts.
Pseudonymous identifiers reduce exposure but do not automatically make a dataset non-sensitive or outside applicable rules. Review linkability, small cohorts, free-text fields, URLs, device metadata, and combinations that can reveal a condition. Never put clinical details or identifiers in feature names, variation labels, or URLs.
A warehouse-native experimentation approach can query approved metrics where the organization already governs them. Architecture does not create compliance on its own; teams still need contracts, access control, auditability, retention rules, security review, and configuration that matches the approved data flow.
Keep unsafe questions out of product experimentation
An experimentation policy should name prohibited or separately governed categories. Product teams should not discover the boundary only after a proposal reaches launch review.
Do not use an ordinary product A/B test to withhold a clinically indicated service, emergency direction, safety warning, accessibility accommodation, required disclosure, or legally protected choice. Do not reduce the visibility of risks to improve completion. Do not randomize a diagnostic or treatment recommendation without the clinical, regulatory, and research framework appropriate to that intervention.
Avoid treatments that exploit fear, urgency, shame, or uncertainty about health. A message can increase appointment conversion while undermining informed choice. Likewise, do not test whether patients tolerate a harder cancellation, more confusing privacy control, or hidden cost. Both variants must meet the organization’s baseline standard for respectful and comprehensible communication.
Clinical AI and decision-support changes need an evaluation program beyond a click-based A/B test. Validate the model offline, examine performance and failure modes across relevant populations, review human factors, and stage deployment with clinical monitoring. An online comparison may contribute evidence only after both treatments meet the safety threshold for exposure.
When an activity may be human-subjects research, follow the institution’s process before enrolling or exposing anyone. HHS research-oversight training states that covered non-exempt human-subjects research requires the applicable review and that informed consent requirements apply unless the IRB authorizes otherwise. The product team should preserve the determination, protocol version, approved treatment, and reporting obligations with the experiment record.
Finally, do not interpret lack of detected harm as proof of safety. Rare adverse events, small vulnerable groups, and outcomes that occur after the experiment window may be underpowered. Use prior evidence, incident monitoring, qualitative reports, and post-rollout surveillance alongside the randomized estimate.
Define patient-centered metrics and guardrails
Healthcare teams need more than a conversion scorecard. Build a measurement hierarchy:
- Primary outcome: the operational or patient-facing result that answers the decision.
- Process diagnostics: steps that explain why the treatment worked or failed.
- Safety guardrails: outcomes that trigger a stop or clinical review.
- Equity checks: predeclared groups where access or benefit could differ.
- Operational guardrails: staffing, wait time, rework, cost, and downstream capacity.
Define the practical threshold before launch. A statistically detectable change may be too small to justify implementation, and a neutral aggregate can hide meaningful harm in a protected or vulnerable group. At the same time, slicing results across many small subgroups increases false-positive risk and can expose sensitive attributes. Predeclare the equity questions that matter and use appropriate privacy and multiple-testing controls.
GrowthBook supports reusable fact tables and metrics so teams can keep definitions reviewable. Use a power analysis for the primary outcome and critical guardrails. If the required sample or duration is unrealistic, do not weaken the standard; use usability research, simulation, staged quality improvement, or a larger treatment contrast.
Create a healthcare experiment review packet
Before launch, the owner should provide one reviewable packet:
- purpose, hypothesis, and operational decision
- classification and required oversight determination
- affected population and exclusion criteria
- clinical, privacy, security, accessibility, and compliance approvals
- treatment screenshots or workflow diagrams
- assignment, exposure, and data-flow design
- primary outcome, diagnostics, guardrails, and equity checks
- sample plan and stopping rule
- rollout stages, monitoring owner, and rollback procedure
- patient or clinician communication plan, if applicable
- documentation and retention plan
Use an approval matrix that names accountable people. Product approval does not replace clinical approval; a privacy review does not settle human-subjects research status; and an IRB determination does not automatically approve the production security architecture.
The WHO clinical-trial best-practices guidance emphasizes ethical standards, regulatory considerations, patient-centered research, transparency, and stakeholder collaboration. Not every healthcare product experiment is a clinical trial, but high-risk work should inherit the same respect for people and evidence.
Build trust into the experimentation program
Start with reversible operational improvements where both experiences are already acceptable. Prove that the team can classify risk, minimize data, validate assignment, monitor safety, and document decisions before expanding scope.
Publish internal rules for what teams may test, what requires added review, and what is out of bounds. Maintain an experiment registry and audit trail. Record neutral and negative results so a new team does not repeat the same risky idea.
GrowthBook can support the controlled delivery and analysis layer through experimentation, feature flags, permissions, and warehouse-defined metrics. The organization remains responsible for the clinical, ethical, legal, privacy, and operational framework around every test.
In healthcare, speed is valuable only when the learning process protects the people whose behavior creates the data.
Build a governed test workflow
Connect controlled releases to reviewable metrics and decision rules while keeping healthcare data in your approved architecture.
Get Started With GrowthBook
The right statistical test is determined by the question and data-generating process, not by which function is easiest to run. Start with the outcome, groups, and dependence structure; the test name comes later.
Z-tests, t-tests, chi-square tests, and analysis of variance (ANOVA) all compare observed data with a null model. They differ in the kind of outcome they model, the uncertainty they estimate, and the number or structure of groups they can compare.
For a simple product experiment, a useful first pass is:
- continuous outcome, two independent groups: usually a Welch two-sample t-test
- binary proportion, two large independent groups: a two-proportion z-test is common
- categorical counts across groups: chi-square test, if expected counts are adequate
- continuous outcome across three or more groups: one-way ANOVA or Welch ANOVA
Those rules are a starting point. Paired observations, clusters, ratios, repeated measures, heavy tails, covariate adjustment, or sequential monitoring require a model that reflects the design.
Choose from the outcome and hypothesis
Write the estimand before choosing a test. An estimand is the quantity the experiment is trying to estimate: a difference in mean revenue, a difference in conversion probability, or an association between two categorical variables.
| Question | Outcome | Common test |
|---|---|---|
| Did average order value change between A and B? | Continuous | Welch two-sample t-test |
| Did signup probability change between A and B? | Binary | Two-proportion z-test |
| Is plan choice associated with variant? | Categorical, 3+ levels | Chi-square test of independence |
| Do mean task times differ across four variants? | Continuous | One-way ANOVA |
| Did the same users' scores change before and after? | Paired continuous | Paired t-test |
The number of groups alone is insufficient. Conversion in four variants is still categorical data; a chi-square or binomial model may fit. Revenue in two groups is continuous; a t-test or regression is more natural.
The University of Michigan's statistical-test guide uses the same sequence: identify variable types and the relationship being tested before selecting a method.
When to use a z-test
A z-test compares a standardized estimate with the standard normal distribution. The classical one-sample z-test for a mean assumes the population standard deviation is known. That condition is unusual in product analytics, where variability is estimated from the current sample.
Z-tests remain common for proportions. In a two-arm conversion experiment, the estimate is:
Under the null of equal proportions and with adequate counts, the standardized difference is approximately normal. This yields a two-proportion z-test.
Use it when:
- the outcome is a binary count summarized as successes and failures
- assignment groups are independent
- sample sizes make the normal approximation credible
- the hypothesis and one- or two-sided direction were set before analysis
Do not rely on a universal “n greater than 30” rule. For rare events, 30 observations can produce almost no successes; for balanced common events, approximation quality can be good. Inspect expected successes and failures and use an exact or model-based method when counts are sparse.
In high-volume online experiments, a normal approximation is also used for many sample means through the central limit theorem. The important question is whether the estimator's sampling distribution and variance calculation are valid for the metric, not whether the raw user values look perfectly normal.
When to use a t-test
A t-test is designed for inference about means when the variance is estimated from sample data. That extra variance uncertainty produces a t distribution with heavier tails than the standard normal, especially at small sample sizes.
For two independent groups, default to Welch's t-test unless equal variance is justified. Welch's version does not assume the two population variances are equal and handles unequal group sizes. NIST's two-sample t-test reference shows the unequal-variance standard error based on each group's sample variance and size.
Use an independent two-sample t-test when:
- the outcome is numeric and the mean is the target
- the two groups contain different experimental units
- observations are independent within the model
- the mean and standard error behave well enough for the sample size
Use a paired t-test when each value has a meaningful partner: the same user's before-and-after score, or deliberately matched units. The analysis reduces each pair to a difference and tests the mean of those differences. Treating paired data as independent discards information and computes the wrong standard error.
The t-test can be sensitive to extreme values because the sample mean and variance are sensitive to them. Product metrics such as revenue or session duration are often skewed. At scale, the mean may still have a usable sampling distribution, but inspect outliers, data quality, and the estimand. Robust inference, transformations, winsorization policies, or bootstrap methods may be more appropriate when a few observations dominate the result.
Reduce variance before launch
Learn how CUPED and covariate adjustment can sharpen experiment estimates without changing the randomized comparison.
Explore Variance Reduction
When to use a chi-square test
Pearson's chi-square statistic compares observed category counts with counts expected under a null hypothesis. Two common forms are:
- goodness of fit: does one categorical distribution match specified probabilities?
- independence or homogeneity: is a categorical outcome distributed the same way across groups?
Suppose an onboarding experiment records three outcomes: completed, skipped, and abandoned. Cross-tabulate outcome by variant. A chi-square test asks whether the outcome distribution is independent of variant.
The test statistic sums (observed - expected)^2 / expected across cells. NIST's chi-square documentation describes the same comparison of binned frequency distributions.
Use a chi-square test when observations contribute counts to mutually exclusive categories and expected cell counts are large enough for the asymptotic approximation. With sparse cells, combine categories only when substantively justified or use an exact method such as Fisher's exact test for a two-by-two table.
A chi-square result says the distributions differ somewhere. It does not provide the most decision-friendly effect estimate by itself. Report category proportions, absolute differences, uncertainty intervals, and the cells contributing to the pattern.
For a binary two-arm experiment, the Pearson chi-square test and a two-sided two-proportion z-test are closely related: under standard conditions, the chi-square statistic with one degree of freedom equals the squared z statistic. Choose the representation that matches the hypothesis and reporting needs.
When to use ANOVA
ANOVA compares variation between group means with unexplained variation within groups. A one-way ANOVA tests the null that all population means are equal across levels of one factor.
Use it for a continuous outcome across three or more independent groups when the global question is whether any mean differs. Classical ANOVA assumes independent errors, normally distributed residuals within the model, and equal variances. Welch ANOVA relaxes the equal-variance assumption; R's 0 implements that approximation.
ANOVA's F-test is an omnibus test. A significant result means at least one mean differs, but it does not identify which one. Use planned contrasts or multiplicity-aware post-hoc comparisons to answer the product question.
ANOVA is more than a rule for “three or more groups.” Multi-factor ANOVA can estimate main effects and interactions in multivariate or factorial experiments. Repeated-measures or clustered data need corresponding error structures rather than a basic one-way calculation.
Why several t-tests are not a substitute for ANOVA
With four variants there are six pairwise comparisons. Testing each at 0.05 creates multiple opportunities for a false positive. An omnibus ANOVA tests one global null first, and planned follow-ups can use Tukey, Holm, Bonferroni, or another procedure appropriate to the family of claims.
The Bonferroni correction is simple and conservative. The right procedure depends on whether the goal is all pairwise comparisons, treatments versus one control, or a small set of preplanned contrasts. Define that family before looking at the ranking.
ANOVA and regression are also two views of the same linear-model machinery. R's 0 documentation describes aov as a wrapper around linear models for experimental designs. Regression is often more flexible when the analysis includes covariates, interactions, or unbalanced data.
Assumptions that change the choice
Before running any of the four tests, verify:
Independence and assignment unit
If the experiment randomizes accounts but analyzes users as independent observations, standard errors will usually be too small. Analyze at the randomization unit or use cluster-aware inference. If users can appear in both groups, repair the assignment or use a model that represents the dependence.
Paired or repeated observations
The same user measured twice is not two independent users. Use a paired test or repeated-measures model. For experiments with many events per user, aggregate to the user level or use appropriate clustered methods.
Outcome distribution and metric construction
Check missingness, zero inflation, extreme tails, ratio denominators, and censoring. A test can be mathematically correct for the supplied numbers while the metric itself misrepresents the user outcome.
Variance assumptions
Prefer Welch's t-test or Welch ANOVA when group variances may differ. Equal sample sizes do not prove equal variance, and a preliminary variance test can introduce another decision layer.
Sample size and sparse cells
Approximate z and chi-square methods need enough information in the relevant cells. Low-frequency guardrails and small segments may need exact methods or longer collection.
A product experimentation decision tree
Use this sequence before opening a statistics package:
- What unit was randomized: user, account, device, session, or region?
- What is the primary estimand: mean, proportion, category distribution, or model coefficient?
- Are groups independent, paired, repeated, or clustered?
- Are there two groups, several groups, or multiple factors?
- Do expected counts and sample sizes support the approximation?
- Are variances, tails, or outliers likely to break the default model?
- How many confirmatory hypotheses can trigger the decision?
- Was the test direction and stopping rule declared before launch?
Then choose the simplest model that answers the exact question. A two-proportion z-test may be perfect for signup conversion, while a t-test handles mean revenue and a chi-square test handles plan mix in the same experiment. Different metrics can require different tests.
Report effects, not only test names
The test produces a statistic and p-value under a null model. The guide to interpreting a t-test p-value shows why that number needs the effect, interval, and degrees of freedom beside it. The product decision needs more:
- the effect estimate in business units
- a confidence or credible interval
- sample sizes and allocation
- baseline and treatment values
- assumption and data-quality checks
- the planned hypothesis family
- practical thresholds and guardrails
GrowthBook's statistics documentation explains the frequentist and Bayesian engines available for experiment analysis. Whichever framework is used, review effect magnitude and uncertainty together. A small p-value can accompany a trivial lift in a huge sample, while a valuable estimated lift can remain uncertain in a small one.
Choose the test by tracing the data back to the experiment design. For three or more continuous-outcome variants, the deeper ANOVA guide covers the omnibus F-test, planned contrasts, and Welch alternative. When the outcome, assignment unit, dependence, and hypothesis are explicit, the difference between z, t, chi-square, and ANOVA becomes a modeling decision rather than a memorization exercise.
Analyze tests with context
Connect experiment assignments to trusted metrics, inspect uncertainty, and keep decision rules visible to the whole team.
Get Started With GrowthBookAn experiment with control plus three variants creates more than one comparison. ANOVA gives the team one principled global test of whether the variants differ before it starts hunting for a winner.
Analysis of variance, or ANOVA, is a family of statistical models for comparing group means and decomposing sources of variation. In a one-way product experiment, the “factor” is the assigned variant and its “levels” are control, B, C, and D.
The basic ANOVA question is deliberately broad: if all variants had the same population mean, would the observed separation among their sample means be surprising relative to the noise within variants?
That question is useful, but incomplete. A significant ANOVA result does not say which variant won, whether the lift is large enough to ship, or whether assumptions and instrumentation are sound. Those conclusions require planned contrasts, uncertainty intervals, and experiment-quality checks.
How ANOVA compares means through variance
ANOVA separates total variability into components:
- between-group variation: how far each group mean is from the overall mean
- within-group variation: how far individual observations are from their group mean
Each sum of squares is divided by its degrees of freedom to produce a mean square. The F statistic is:
Under the null hypothesis that all group means are equal, both quantities estimate the same underlying error variance, so their ratio should often be near 1. When group means are separated relative to the residual noise, F grows.
NIST's one-way ANOVA explanation describes this as comparing the level mean square with the residual mean square. The p-value is the probability, under the null model and assumptions, of an F statistic at least as large as the observed one.
For k groups and N total observations, one-way ANOVA usually has:
The numerator asks how much the k means vary. The denominator pools information about variability inside the groups.
A four-variant experiment example
Suppose a SaaS team tests four onboarding flows and measures projects created per eligible account during the first week.
| Variant | Accounts | Mean projects | Standard deviation |
|---|---|---|---|
| Control | 1,000 | 2.30 | 1.80 |
| B | 1,020 | 2.42 | 1.84 |
| C | 990 | 2.61 | 1.91 |
| D | 1,010 | 2.36 | 1.79 |
The null hypothesis is:
The alternative is that not all four means are equal. Notice what it does not say: “C is best.” The global alternative includes any pattern where at least one mean differs.
If the F-test rejects the null, the team should evaluate the comparisons it planned. It might compare every treatment with control, or test one contrast between the current flow and the average of three new concepts. The comparison plan should reflect the decision, not the visual ranking in the finished dashboard.
Make multiple tests trustworthy
See how experimentation leaders plan hypotheses, guardrails, and review practices when a result surface contains many possible claims.
Watch the Trustworthy Experiments Talk
Why not run every pairwise t-test?
Four groups create six pairs. If the team runs six independent tests at alpha 0.05 and treats any significant result as proof, the probability of at least one false positive across the family can exceed 0.05.
ANOVA gives one global test of the equality of all means. It also estimates residual variation using all groups, which can be more efficient than estimating it afresh for each pair under the classical equal-variance model.
The global test does not eliminate multiplicity in follow-up comparisons. R's Tukey HSD documentation explicitly notes that ordinary t-tests inflate the probability of a false declaration across a family. Choose the follow-up procedure for the comparisons the decision actually needs:
- every pair: Tukey-style simultaneous comparisons
- every treatment versus control: Dunnett-style comparisons
- a few planned product questions: predeclared contrasts with a suitable adjustment
- a conservative small family: a Bonferroni or Holm correction
An omnibus test can also be nonsignificant while one carefully planned contrast is persuasive, because the hypotheses and power differ. Decide before launch whether the global null or a treatment-versus-control contrast is the primary decision test.
Unequal group sizes do not automatically invalidate ANOVA, but they make the variance assumption and contrast plan more consequential. If allocation is intentionally uneven, power the smallest comparison that drives the decision and preserve the assignment probabilities. When variances and sample sizes both differ, classical pooled ANOVA can behave poorly; Welch ANOVA or a regression with suitable standard errors is usually easier to defend.
Planned contrasts can also use product structure that the global test ignores. Instead of comparing every pair, a team might compare control with the average of three related treatments, or compare two low-intensity treatments with two high-intensity treatments. A small set of predeclared contrasts often answers the business question with more power and clearer multiplicity control than an exhaustive winner search.
ANOVA assumptions in experiments
The familiar one-way fixed-effects model can be written as:
Classical inference depends on the residuals and design, not on a requirement that the combined raw outcome form one bell curve. NIST's model reference assumes independent, normally distributed errors with mean zero and common variance.
Independent observations
The analysis unit must respect randomization. If accounts are assigned but every user within an account is treated as independent, the standard error ignores clustering. Aggregate at the account level or use cluster-robust or hierarchical methods.
Repeated events from one user create the same problem. Ten sessions from one user do not carry the same independent information as ten users.
Appropriate residual behavior
ANOVA is often robust to moderate non-normality with balanced, sufficiently large groups, but severe skew, outliers, censoring, or zero inflation can make the mean unstable or the F approximation unreliable. Diagnose residuals and assess whether the mean is still the business estimand.
Equal variance for classical one-way ANOVA
Classical ANOVA assumes a common population variance. This can fail when a treatment changes both the mean and spread, or when groups serve different traffic mixes. Unequal group sizes make the problem more consequential.
SciPy's 0 supports Welch ANOVA when equal_var=False. Welch's method relaxes equal population variances and adjusts the degrees of freedom.
Correct outcome model
ANOVA targets a continuous mean. Conversion is binary; event counts are discrete; time-to-churn can be censored. Large-sample mean inference can sometimes work, but logistic, Poisson or negative-binomial, survival, or other generalized models may better represent the outcome and produce interpretable effects.
One-way, two-way, and repeated-measures ANOVA
“ANOVA” names a family rather than one calculation.
One-way ANOVA
One categorical factor with multiple levels, such as four assigned onboarding variants. This is the usual A/B/n example.
Two-way or factorial ANOVA
Two controlled factors, such as headline and layout. The model estimates each main effect plus their interaction. The interaction asks whether one factor's effect changes with the other. This is central to a properly designed multivariate test.
Repeated-measures ANOVA
The same units are observed under multiple conditions or times. Dependence is part of the design and must be modeled. A basic independent one-way ANOVA is invalid for repeated measurements.
ANCOVA
Analysis of covariance adds continuous covariates to the group comparison. In randomized experiments, pre-experiment covariates can improve precision when they are chosen and measured without post-treatment contamination. GrowthBook's guide to variance reduction explains the same motivation in online experimentation.
Run one-way ANOVA in Python
At the action boundary, keep one numeric observation per independent analysis unit in each group. In SciPy:
Before running it, confirm that rows match the randomization unit and missing values have a documented policy. Afterward, inspect group summaries and residual behavior. The p-value alone cannot reveal a broken exposure join or a few enormous outliers.
In R, aov(outcome ~ variant, data = experiment) fits the classical model. R documents 1 as a linear-model interface, which helps explain why ANOVA, regression, and contrasts are closely connected.
Interpret the ANOVA table
A standard output contains:
- degrees of freedom
- sum of squares
- mean square
- F statistic
- p-value
Suppose the output reports F(3, 4016) = 6.8, p < 0.001. Under the model, the observed ratio of between-variant to within-variant variation is unlikely if all four population means are equal. It does not mean every treatment beats control or that any effect is commercially important.
Add the quantities the product decision needs:
- each mean and sample size
- differences from control in original units
- simultaneous or comparison-specific intervals
- an effect-size measure when useful
- guardrail and data-quality results
- the follow-up comparison method
Avoid ranking noisy means without uncertainty. The highest observed variant has benefited from both its true effect and sampling variation, especially when many variants were screened.
Common ANOVA mistakes
Treating events as independent users
Repeated events make the nominal sample size huge and uncertainty too narrow. Preserve the assignment unit.
Using ANOVA for every metric shape
The word “variant” does not imply ANOVA. Match the outcome distribution and estimand to a model.
Checking assumptions after selecting a winner
Write the model, outlier policy, transformation, and variance choice before the ranking is visible. Result-driven switching creates hidden researcher degrees of freedom.
Treating a significant F-test as a winner declaration
Follow with the planned contrasts. The omnibus test only rejects equality of all means.
Ignoring practical significance
A very large experiment can detect a tiny difference. Compare intervals with a minimum practical effect and account for implementation cost and guardrails.
Use ANOVA as part of an experiment plan
Before launch, specify the factor and levels, independent unit, primary continuous outcome, minimum effect, sample-size plan, variance assumption, global or contrast hypothesis, comparison family, and stopping rule.
Then verify assignment and exposure before interpreting the model. A sample ratio mismatch can signal that observed group counts no longer reflect the planned randomization. No F-test can repair biased exposure data.
ANOVA is valuable because it turns a field of variant means into a structured model of signal and noise. The broader z-test, t-test, chi-square, and ANOVA guide shows when the outcome and hypothesis call for another member of that family. Use the omnibus test for the global question, planned contrasts for the decision, and effect estimates for practical judgment. That sequence makes a multiple-variant test easier to defend than a dashboard full of uncoordinated p-values.
Compare variants with discipline
Run controlled experiments, connect trusted metrics, and review treatment effects and uncertainty in one shared workflow.
Start With GrowthBookReady to ship faster?
No credit card required. Start with feature flags, experimentation, and product analytics—free.