LaunchDarkly: Feature Flagging Platform Explained

LaunchDarkly is the most widely recognized name in feature flagging, and for some teams it's genuinely the right choice — but "widely recognized" and "right for your team" are two different things that often get conflated during vendor evaluations.
The platform is built for a specific kind of organization, and understanding exactly what it does well, what it costs, and where it falls short will save you from a procurement decision you'll regret at renewal time.
This article is written for engineers, PMs, and technical leads who are actively evaluating LaunchDarkly — whether you're considering it for the first time or trying to decide if it's still the right fit as your team scales. Here's what you'll find inside:
- How LaunchDarkly actually works — the mechanics of flag evaluation, targeting, and progressive rollouts
- What the platform includes — its three product pillars (Release, Observe, Iterate), AI Configs, and enterprise tooling
- When it makes sense — the team profiles and use cases where LaunchDarkly's premium is justified
- What it costs and what can go wrong — pricing structure, reliability history, and technical constraints that matter at scale
- What the alternatives look like — open-source and commercial options, and how they compare across the dimensions that actually drive decisions
Each section is written to give you a specific, honest picture of one part of the platform. By the end, you'll have enough to know whether LaunchDarkly fits your situation — or whether a different tool gets you 90% of the capability at a fraction of the cost and complexity.
LaunchDarkly's core mechanic: decoupling deployment from release
LaunchDarkly is a feature management and runtime control platform built around a single organizing idea: the moment you deploy code and the moment you release a feature to users do not have to be the same event.
That separation — deployment and release — is the mechanical foundation of everything the platform does. Code ships to production continuously; what users actually see is controlled independently, in real time, through feature flags.
The core concept: separating deployment from release
In traditional release workflows, deploying code and releasing functionality are coupled. If something goes wrong, the blast radius is the entire deployment. Feature flags break that coupling by wrapping functionality in conditional logic — an if-else evaluation that determines, at runtime, whether a given user sees the new behavior or the old one. The code is already in production; the flag is the switch.
LaunchDarkly describes itself as "the runtime control platform for releases, AI behavior, and customer experience in real time, no redeploys required." That framing is operationally precise: the platform's value is not in how you write or deploy code, but in how you control what runs after it's deployed.
For engineering teams managing continuous delivery pipelines, this means you can merge and deploy freely while keeping unfinished or risky features dark until you're ready to expose them — to a test group, a specific segment, or your entire user base.
Flag evaluation: a four-step runtime loop with no redeployment
The mechanics follow a four-step sequence: install an SDK, create a flag in the LaunchDarkly UI, wrap the relevant code path in a flag evaluation call, then control the flag's behavior at runtime without touching the codebase again. Flag changes propagate globally in under 200 milliseconds — no redeployment, no service restart.
One thing worth knowing about how LaunchDarkly's client-side SDKs work: they don't calculate flag values on the device. Instead, the SDK sends a request to LaunchDarkly's servers, which evaluate the targeting rules and send back the result.
This keeps the evaluation logic centralized, but it means your client-side flag behavior depends on a network call to LaunchDarkly's infrastructure. All SDKs also send evaluation events back to LaunchDarkly, which is how the platform tracks usage and supports its MAU-based billing model.
For teams with strict data residency requirements or who want to reduce external network dependency, LaunchDarkly offers an optional Relay Proxy — though it adds operational overhead to maintain.
Targeting, segmentation, and progressive rollouts
Beyond simple on/off switches, LaunchDarkly supports targeting rules that let you evaluate flags differently for different users or segments. You can roll a feature out to 5% of users, then 25%, then 100% — adjusting the percentage in real time based on what you're observing. You can target by user attributes, by custom context keys, or by pre-defined segments. This is the mechanism behind progressive delivery: instead of a binary release, you're managing a controlled expansion of exposure.
The same targeting infrastructure feeds into experimentation. You define a flag, attach metrics, specify a sample audience, and LaunchDarkly records evaluation data to let you compare variants. The targeting model is flexible, and the full implications of its multi-context architecture are covered in the constraints section later in this article.
40 trillion evaluations per day: what LaunchDarkly's scale actually proves
The scale at which LaunchDarkly operates is worth stating plainly, because it's the most direct evidence that the platform works in production environments: 40 trillion flag evaluations per day, flag updates propagating worldwide in under 200 milliseconds, support for 35+ native SDKs, and 80+ integrations with the broader engineering toolchain. These aren't theoretical benchmarks — they reflect the platform's actual production load across its customer base.
The three product pillars LaunchDarkly organizes around — Release, Observe, and Iterate — map to the lifecycle of a controlled feature rollout: ship it safely, watch what happens, and use data to decide what to do next.
Paramount, one of LaunchDarkly's enterprise customers, credits the platform with a 100X improvement in developer productivity and a shift to 6–7 production deployments per day. That outcome is a reasonable illustration of what decoupling deployment from release actually enables at scale: teams stop treating deployments as high-stakes events and start treating them as routine operations.
LaunchDarkly's three product pillars: Release, Observe, and Iterate
Those three pillars — Release, Observe, and Iterate — are not just marketing labels. Each targets a different phase of the software delivery lifecycle, and understanding how they divide the feature set helps product managers and technical leads map their actual needs to specific product areas, rather than evaluating the platform as a monolithic "feature flagging tool."
The Release pillar: controlled deployment and progressive delivery
The Release pillar is where LaunchDarkly has the deepest capability and the longest track record. Beyond basic flag on/off controls, it includes progressive rollouts with attribute-based targeting — account ID, geography, device type, plan level — as well as persistent cohorts and reusable segments that can be combined into complex targeting logic without duplicating configuration across flags.
Enterprise release controls go further. Prerequisite flags and flag dependencies allow teams to define evaluation sequences, so a downstream flag won't activate unless upstream conditions are met. Scheduled releases let teams set future activation times without manual intervention at release hour. Approval workflows with custom roles add a governance layer, requiring sign-off before flag changes reach production. Code references with flag archive automation help teams track which flags are still referenced in the codebase and clean up stale ones systematically.
Named product features in this pillar include Release Automation, the Launch Insights dashboard, a Mobile Lifecycle Assistant for managing flag lifecycles in mobile app releases, and a Migration Assistant for teams moving from one flag architecture to another. Multi-environment support is built into the platform natively, which matters for teams managing separate staging, canary, and production environments under the same flag configuration.
The Observe pillar: automated response to production signals
The Observe pillar closes the loop between flag delivery and production health. LaunchDarkly connects to your existing monitoring tools — New Relic, Datadog, and similar platforms — and can automatically turn off a feature flag if error rates or response times spike past a threshold you set. You define the conditions; the platform responds. You don't need someone watching dashboards at 2am to catch a problem and manually flip the switch.
LaunchDarkly's streaming architecture, which scores at the top of independent evaluations for this capability, enables flag updates to propagate in under 200 milliseconds globally — which is what makes automated rollback practical rather than theoretical. The Launch Insights dashboard surfaces feature performance data to give teams visibility into what's running, where, and with what effect.
The Iterate pillar: experimentation and feature validation
LaunchDarkly offers A/B testing and experimentation capabilities, but this is where the platform's positioning gets more nuanced. Experimentation is sold as an add-on rather than included in base pricing, which affects the total cost calculation for teams that want integrated feature validation alongside flag management.
The platform supports both Bayesian and frequentist statistical methods. Teams evaluating the experimentation depth should verify current support for sequential testing and CUPED compatibility against their specific use cases, as some capabilities have been in active development. One architectural constraint worth noting: there is a limit of one active experiment per flag, which affects how teams structure concurrent tests on the same feature surface.
AI Configs: applying runtime control to prompt and model management
The most recent expansion of LaunchDarkly's feature set is AI Configs, a product area specifically designed for AI prompt and model management. The practical scope is illustrated by the tutorials LaunchDarkly has published: migrating a hardcoded LangGraph agent to AI Configs, building AI Config CI/CD pipelines with automated quality gates, offline evaluation of RAG-grounded answers, and using LLM-as-judge evaluators for AI output quality. OpenTelemetry integration for LLM applications is also part of this layer.
The underlying idea is that the same runtime control problem LaunchDarkly solves for feature flags — changing behavior in production without redeployment — applies directly to AI systems, where prompt versions, model selections, and inference parameters need to be adjusted and validated without a full code release cycle.
Enterprise tooling: integrations, governance, and SDKs
LaunchDarkly supports 35+ SDKs and 80+ integrations, covering the major CI/CD platforms, observability tools, and data pipelines that enterprise engineering teams already operate. Role-based access control, audit logs, and SSO/SAML support are part of the governance layer.
In an independent 50-criteria evaluation of enterprise feature flagging platforms, LaunchDarkly scored 407 out of 500, leading all platforms assessed — with particular strength in flag dependency management, approval workflows, and release lifecycle tooling.
One architectural note for teams with strict data residency or self-hosting requirements: LaunchDarkly is a cloud-only platform. The Relay Proxy can reduce direct network dependency on LaunchDarkly's infrastructure, but full self-hosting is not available — a distinction that matters for regulated industries and teams with specific deployment constraints.
LaunchDarkly's strongest fits — and where the premium doesn't hold
Understanding what LaunchDarkly is built for is only useful if you're honest about whether your team actually matches that profile. The platform doesn't pretend to be a universal fit, and the clearest way to evaluate it is to ask whether your operational reality aligns with what it's optimized for. For many teams, the honest answer is no — and that's worth knowing before you start a procurement process.
Enterprise compliance and regulated industries
The single most defensible reason to choose LaunchDarkly over any other feature flag platform is FedRAMP Moderate Authorization to Operate. No other major feature flag vendor holds this certification, which makes LaunchDarkly the only viable option for federal government, DoD, and defense contractor workloads where FedRAMP compliance is a procurement requirement rather than a preference. The platform maintains a dedicated federal cloud instance specifically for these environments.
Beyond FedRAMP, LaunchDarkly scores at the top of enterprise governance evaluations across security, compliance, and operational maturity. For organizations in regulated industries where feature flag infrastructure needs to pass security reviews, audit trails matter, and change management is non-negotiable, LaunchDarkly's compliance portfolio is genuinely difficult to match.
The SaaS-only architecture is a real tradeoff — there's no full self-hosting option — but for federal buyers, the compliance certifications typically outweigh the data residency concerns that would otherwise make cloud-only a dealbreaker.
DevOps and release control teams
LaunchDarkly earns its strongest marks in the scenarios it was originally designed for: giving engineering teams precise, real-time control over what gets released to whom and when. Gradual rollout strategies, user targeting and segmentation, and SDK coverage across 35+ languages all score at the top of vendor evaluations — and these aren't just checkbox features. The platform handles release scenarios ranging from simple UI changes to database migrations and API layer transitions, which is the range of use cases the AWS workshop documentation covers explicitly.
The Guarded Releases capability, which reached general availability at Galaxy 2025, adds automated rollback to this picture — meaning teams can define rollback conditions and let the platform respond without manual intervention. Combined with Workflows for automated rollout sequencing and Segments for user group management, LaunchDarkly gives DevOps-heavy teams a level of release orchestration that goes well beyond toggling flags on and off.
One thing worth flagging honestly: setup time runs days to weeks rather than hours. For a small team, that's friction. For a large engineering organization with structured onboarding processes and cross-team coordination requirements, it's appropriate — the complexity reflects the governance model, not a product deficiency.
Integration-heavy enterprise environments
If your engineering organization already runs a mature DevOps toolchain — observability platforms, ITSM systems, IaC pipelines, incident management tools — LaunchDarkly's 80+ integration ecosystem is a meaningful differentiator. The practical integration use cases are well-documented: routing flag change notifications to Slack or Teams, correlating flag changes with performance anomalies in APM tools like New Relic or Dynatrace, and automating performance management responses via flag triggers.
The ServiceNow connector is particularly relevant for enterprises where feature flag changes need to flow through formal change management processes — this is a gap in most competing platforms. Official Terraform provider support matters for teams managing infrastructure as code, where a community-authored provider introduces maintenance risk.
Where LaunchDarkly is likely overkill
For small-to-mid-size teams, cost-sensitive organizations, or teams whose primary need is experimentation depth rather than release control, LaunchDarkly's premium is harder to justify. The platform's pricing scores near the bottom of vendor evaluations, and the MAU-based cost model becomes unpredictable at scale — a topic covered in more detail in the pricing section of this article. Teams that need self-hosting for data residency requirements are also not well-served here, given the SaaS-only architecture.
The honest framing is this: LaunchDarkly justifies its premium for organizations that need the broadest compliance portfolio, the deepest integration ecosystem, and enterprise governance with formal change management support.
If your team doesn't need FedRAMP, doesn't run an 80-tool DevOps stack, and isn't coordinating flag changes across multiple engineering teams with audit requirements, there are platforms that deliver comparable feature flag functionality at significantly lower cost and complexity.
LaunchDarkly pricing, reliability concerns, and known limitations
LaunchDarkly is a mature, capable platform — but the costs, architectural dependencies, and technical constraints that matter most tend to surface after adoption, not during the sales process. Engineering managers and procurement leads evaluating the platform at scale need a clear-eyed picture of what they're committing to.
Pricing model and cost predictability
LaunchDarkly's Foundation plan is billed on two independent dimensions: $12 per service connection per month and $10 per 1,000 client-side monthly active users. Service connections count every microservice, replica, and environment connected to the platform in a given month. The free Developer tier caps at 5 service connections and 1,000 MAUs; enterprise and higher tiers move to custom pricing with no published rates.
The structural problem is that both billing dimensions scale independently. As a microservice architecture grows and a user base expands, service connection counts and MAU counts both increase simultaneously — and neither is easy to predict at budget time. Experimentation compounds this further: it is not included in the base pricing on any tier and is sold as a separate paid add-on. For teams that want to run A/B tests alongside their feature flags, that's a meaningful additional line item.
In practice, annual contracts range from roughly $20,000 to $120,000 depending on team size and usage complexity, according to procurement data from Spendflo. Third-party contract intelligence from Vendr puts the median Enterprise contract at approximately $72,000 annually, though enterprise pricing is entirely custom and negotiated.
One user review circulating in the practitioner community captures the renewal dynamic bluntly: "they can literally charge any amount of money and your alternative is having your own SaaS product break." That's an extreme framing, but it points to a real structural issue — the vendor lock-in dynamics are covered in detail in the next section.
Cloud-only architecture and vendor lock-in
LaunchDarkly does not offer a full self-hosting option. The platform operates as a SaaS-first control plane, meaning your flag evaluation infrastructure depends on LaunchDarkly's managed services. A Relay Proxy is available to reduce direct network dependency and improve latency, but it adds its own operational complexity to maintain.
The lock-in risk is architectural. Feature flag SDK calls get embedded across every service in a codebase over time, making migration a multi-month effort even with a clear plan. That dependency gives LaunchDarkly meaningful pricing leverage at renewal — a dynamic worth factoring into any long-term evaluation.
Reliability history and the October 2025 outage
LaunchDarkly's status history includes over 800 tracked incidents since November 2019, according to platform comparison data from a competitor source — readers should verify against LaunchDarkly's own status page at status.launchdarkly.com. The most significant recent incident occurred in October 2025, when approximately 99% of server-side SDKs globally were affected for roughly 24 hours.
The structural reason for this exposure is that LaunchDarkly's SDKs are network-dependent by default — flag evaluation requires connectivity to LaunchDarkly's infrastructure unless the Relay Proxy is deployed and properly configured. For teams running feature flags on critical paths, that dependency is an operational risk that deserves explicit mitigation planning.
Targeting architecture and experimentation limits that surface after adoption
Three constraints are worth flagging for teams with complex targeting or experimentation needs.
LaunchDarkly's multi-context targeting model — which allows flags to target users, organizations, devices, and other entities simultaneously — requires upfront schema design decisions. Adding new targeting contexts later means SDK-level changes and cross-team coordination, which can slow down targeting rule changes in practice.
On the experimentation side, only one experiment can run per feature flag at a time. Teams running high-velocity testing programs may find this constraining as flag counts and experiment counts grow. LaunchDarkly's warehouse-native experimentation is currently restricted to Snowflake and requires elevated account permissions to configure.
Percentile analysis is in beta and is not compatible with CUPED, and funnel metrics are limited to average-based analysis — limitations that matter for teams with sophisticated statistical requirements.
The stats engine itself lacks methodological transparency: experiment results cannot be audited or independently reproduced, which is a meaningful constraint for organizations that need to verify their experimentation program's statistical foundations.
LaunchDarkly alternatives: four distinct strategies, not a linear ranking
If you've worked through LaunchDarkly's pricing model, reliability history, and architectural constraints, you're probably already thinking about what else is out there. The honest answer is that no single platform wins across every dimension — the right choice depends on which trade-offs your team can live with and which ones you can't.
A 50-criteria weighted analysis of the major platforms found that the top contenders represent "four distinct strategies," not a linear ranking. That framing is worth keeping in mind as you evaluate.
Open-source options: Unleash, Flagsmith, and GrowthBook
The three primary open-source alternatives each occupy a different position in the trade-off space.
Unleash is the simplest to operate — it runs on PostgreSQL with a stateless API layer, which makes self-hosting straightforward. It scores 9/10 on self-hosting and uses seat-based pricing that doesn't charge for MAUs or service connections, a direct structural contrast to LaunchDarkly's model. Unleash claims roughly a quarter of LaunchDarkly's cost for most users, though that figure comes from Unleash's own marketing and should be treated accordingly. The significant limitation: Unleash scores 2/10 on experimentation. It's a strong choice for teams that need reliable flag delivery and cost control but don't need statistical analysis built in.
Flagsmith follows a similar pattern — 9/10 on self-hosting (Docker, Kubernetes, or Django-native), 2/10 on experimentation, and a particular strength in remote configuration and identity-based targeting. If your primary use case is feature flags and remote config rather than A/B testing, Flagsmith is worth evaluating seriously.
GrowthBook is built as a unified platform covering feature flags, experimentation, targeting, and warehouse-native analysis under a single deployment. Unlike Unleash and Flagsmith, which are primarily feature flag platforms, GrowthBook includes the full experimentation stack — Bayesian, frequentist, sequential testing, CUPED variance reduction, post-stratification, bandits, and sample ratio mismatch detection — as core platform capabilities available on every plan, not sold as add-ons.
The self-hosted version is free with no seat limits under an MIT license. The architectural cost is real: GrowthBook requires MongoDB and optionally Redis, making it more operationally complex than Unleash. It scores 8/10 on self-hosting versus Unleash's 9/10.
In a weighted 50-criteria analysis, GrowthBook vs LaunchDarkly are within 9 points of each other (939 vs. 948), with GrowthBook's unified platform leading on experimentation depth and pricing transparency while LaunchDarkly leads on integrations and compliance portfolio. Median Enterprise contract benchmarks from Vendr-sourced data put GrowthBook around $50K/year versus LaunchDarkly's approximately $72K/year, though both figures vary by contract and should be treated as reference points rather than quotes.
Commercial alternative: Statsig
Statsig is the closest commercial peer to LaunchDarkly in terms of scale and experimentation depth. It operates at over a trillion events per day and offers strong statistical capabilities. For teams that want SaaS convenience and don't need self-hosting, Statsig is a credible option.
Two considerations matter here: Statsig cannot be self-hosted, and the OpenAI acquisition introduces uncertainty for regulated industries and EU-based teams with data residency requirements. Optimizely appears on LaunchDarkly's own comparison page as a named competitor, but there isn't comparable scoring data available to assess it on the same dimensions — worth investigating independently if it's on your shortlist.
The four axes that actually separate these platforms
Four axes tend to separate the alternatives in practice, and they don't all point in the same direction.
The most immediately visible is the pricing model: LaunchDarkly charges per MAU, seat, and service connection, which becomes unpredictable at scale, while Unleash and GrowthBook use seat-based models with no usage-based charges, and Statsig is event-based. Self-hosting availability draws a clean line between the options — LaunchDarkly and Statsig are SaaS-only, whereas Unleash, Flagsmith, and GrowthBook all support full self-hosting, which matters for data residency requirements and teams that can't accept vendor-managed infrastructure on critical paths.
Experimentation depth is where the platforms diverge most sharply: LaunchDarkly sells experimentation as a paid add-on, and its stats engine does not allow results to be audited or independently reproduced — a transparency gap that matters for teams with rigorous methodological requirements.
Finally, data transparency separates platforms architecturally: warehouse-native approaches, where every metric and result is backed by inspectable SQL, give teams with strict audit requirements a fundamentally different level of control than platform-managed analytics pipelines that can fall out of sync with your actual data.
Migrating from LaunchDarkly
If you're already on LaunchDarkly and reconsidering, the migration path is more tractable than it might appear. GrowthBook offers a dedicated LaunchDarkly flag importer tool that pulls in your projects, environments, feature flags, targeting rules, fallback values, rollouts, and prerequisite features directly via the LaunchDarkly REST API. The process is a two-step operation: fetch from LaunchDarkly, review the preview, then import to GrowthBook. After that, you replace the LaunchDarkly SDK in your application with the equivalent GrowthBook SDK.
For large accounts with many flags, the fetch step may take several minutes due to rate limiting — GrowthBook's importer includes configurable settings to manage this. Setup time for open-source alternatives is generally measured in hours rather than the days-to-weeks typical of a LaunchDarkly implementation, according to GrowthBook's own comparison documentation. The main migration cost is the SDK swap across your codebase, which is the same effort regardless of which alternative you choose.
Making the call: when LaunchDarkly's premium is defensible and when it isn't
By this point, you have enough to make a structured decision. The question isn't whether LaunchDarkly is a good platform — it is — but whether it's the right platform for your team's specific situation. Here's how to think through that.
LaunchDarkly is the right fit if your team needs enterprise governance and compliance
LaunchDarkly's premium is most defensible in three scenarios. First, if FedRAMP Moderate compliance is a hard requirement, LaunchDarkly is currently the only major feature flag vendor with that certification. There is no open-source or lower-cost alternative that satisfies this requirement today. Second, if your engineering organization runs a mature DevOps toolchain with 50+ integrations and needs formal change management through ServiceNow or similar ITSM platforms, LaunchDarkly's integration depth is genuinely difficult to replicate. Third, if you're coordinating flag changes across dozens of engineering teams with audit trail requirements, approval workflows, and scheduled release governance, the platform's enterprise release controls are purpose-built for that operational model.
In these scenarios, the $72K median annual contract is a reasonable price for infrastructure that handles a genuinely hard problem at scale.
When a LaunchDarkly alternative might serve you better
Outside those three scenarios, the calculus shifts. If your team's primary need is experimentation depth alongside feature flags — running A/B tests, measuring feature impact, and building a culture of data-driven product decisions — LaunchDarkly's add-on pricing model and limited stats engine transparency make it a poor fit. Platforms that include experimentation as a core capability on every plan, with auditable statistical methods and warehouse-native analysis, deliver more value at lower cost for this use case.
If self-hosting is a requirement — whether for GDPR compliance, air-gapped environments, or simply the operational preference to keep flag evaluation infrastructure inside your own systems — LaunchDarkly's SaaS-only architecture is a structural disqualifier. The Relay Proxy reduces network dependency but doesn't change the fundamental data flow.
If cost predictability matters at your scale, the MAU-plus-service-connection billing model deserves careful modeling before you commit. Teams with growing microservice architectures and expanding user bases have found that both dimensions increase simultaneously in ways that weren't obvious at contract time.
Turning this evaluation into a decision: trial, audit, or migrate
The practical next step depends on where you are in the process:
- If you're evaluating LaunchDarkly for the first time: Start with a free Developer account to validate the SDK integration and flag evaluation mechanics against your actual stack. Then model your projected MAU and service connection counts at 12 and 24 months before signing an annual contract.
- If you need FedRAMP compliance: LaunchDarkly is likely your only viable option among major vendors. Request access to their federal cloud instance and validate the compliance documentation against your specific requirements.
- If you're already on LaunchDarkly and concerned about cost trajectory: Audit your current service connection count and MAU trend before your next renewal. If both are growing faster than your team headcount, the cost curve will continue to steepen. Use that data to negotiate or to build a migration business case.
- If you need self-hosting or warehouse-native experimentation: Evaluate GrowthBook's unified platform — feature flags, A/B testing, and warehouse-native analysis are all included under a single deployment. The dedicated LaunchDarkly importer makes the flag migration mechanical rather than manual.
- If you need reliable flag delivery without experimentation: Unleash or Flagsmith are worth a direct evaluation. Both support full self-hosting, use predictable seat-based pricing, and handle the core progressive delivery use case without the complexity or cost of a full enterprise feature management platform.
The right answer depends on your team's actual requirements — compliance portfolio, experimentation ambitions, data residency constraints, and cost tolerance. This article has tried to give you the specific, honest picture of each dimension. The decision is yours to make with that information in hand.
Related reading
Related Articles
In healthcare, “Can we randomize it?” is the wrong first question. Start with “Could either experience change care, rights, privacy, or access?”
A/B testing can improve digital intake, appointment access, patient education, clinician workflows, and administrative operations. It can also create unacceptable risk when teams treat a clinical or consent decision like an ordinary conversion funnel.
The difference is not the label on the method. A/B tests are randomized experiments. What matters is the treatment, purpose, affected population, data flow, and oversight required in the organization and jurisdiction. This guide provides a practical product framework, not a substitute for legal, clinical, privacy, security, or institutional review.
Draw the boundary before designing variants
Create an intake step that classifies the proposed change before anyone builds a treatment. At minimum, ask:
- Can the change alter diagnosis, treatment, triage, dosage, or clinical recommendations?
- Can it delay or discourage access to care, accommodations, or urgent help?
- Does it change informed consent, privacy choice, required disclosure, or patient cost?
- Does it use protected or sensitive health information for assignment or measurement?
- Does it include children, people in crisis, or another population requiring added protection?
- Is the purpose internal quality improvement, or is it designed to contribute to generalizable knowledge?
- Could the software function fall within medical-device or clinical decision-support oversight?
The HHS quality-improvement guidance says many activities limited to improving patient care and collecting operational data are not research under the cited human-subjects regulations. It also states that some quality-improvement activities can have a research purpose, in which case human-subject protections may apply. A product team should not make that determination informally; route it to the organization’s authorized office.
Likewise, software that influences clinical decisions is not automatically an ordinary product surface. The FDA’s January 2026 clinical decision-support guidance explains that some software functions are excluded from the device definition while other patient- or caregiver-facing functions can remain subject to digital-health policy. Clinical and regulatory owners need to classify the function before experimentation.
Start with lower-risk operational questions
The safest early program tests reversible changes where both variants meet the same clinical, accessibility, privacy, and disclosure requirements.
Appointment reminder timing
Compare 2 approved reminder schedules or message structures to reduce missed appointments. Keep required details, opt-out behavior, language support, and urgent-contact instructions constant.
Use completed appointments or timely rescheduling as the primary outcome. Track cancellations, patient contacts, message delivery, opt-outs, wrong-recipient risk, and differences across language, age, disability, or access groups. A higher click rate is not enough if no-show rates or trust worsen.
Patient portal navigation
Test whether a clearer information architecture helps people complete a high-value administrative task, such as finding results, updating insurance, or sending a non-urgent message. Preserve emergency guidance and clinical escalation paths in both variants.
Measure successful task completion and time to completion. Guard against repeated navigation, abandonment, accessibility failures, mistaken message routing, and increased call-center burden. Use usability testing before the A/B test to catch failures randomization should never expose.
Administrative form sequence
Compare a long form with a staged flow, or test the order of non-clinical fields. Do not omit information needed for safe care, billing transparency, consent, or legal compliance.
Measure accurate completion, not just submission. Track validation errors, correction rates, staff rework, abandonment, and time to appointment. If the treatment collects sensitive data, confirm necessity and access controls before launch.
Educational content layout
Test 2 ways to present the same clinician-approved information: summary-first versus stepwise, text plus illustration versus text alone, or a clear action checklist versus a dense paragraph. Keep the medical meaning, risks, contraindications, and escalation advice equivalent.
Use a comprehension or appropriate next-action metric when feasible. Page time and clicks can be misleading. Accessibility, language quality, and comprehension across health-literacy levels belong in the guardrail plan.
Review the design before launch
Use a trustworthy experiment-design session to pressure-test metrics, safety checks, and decision rules before exposing patients or clinicians.
Watch the Experiment Design Session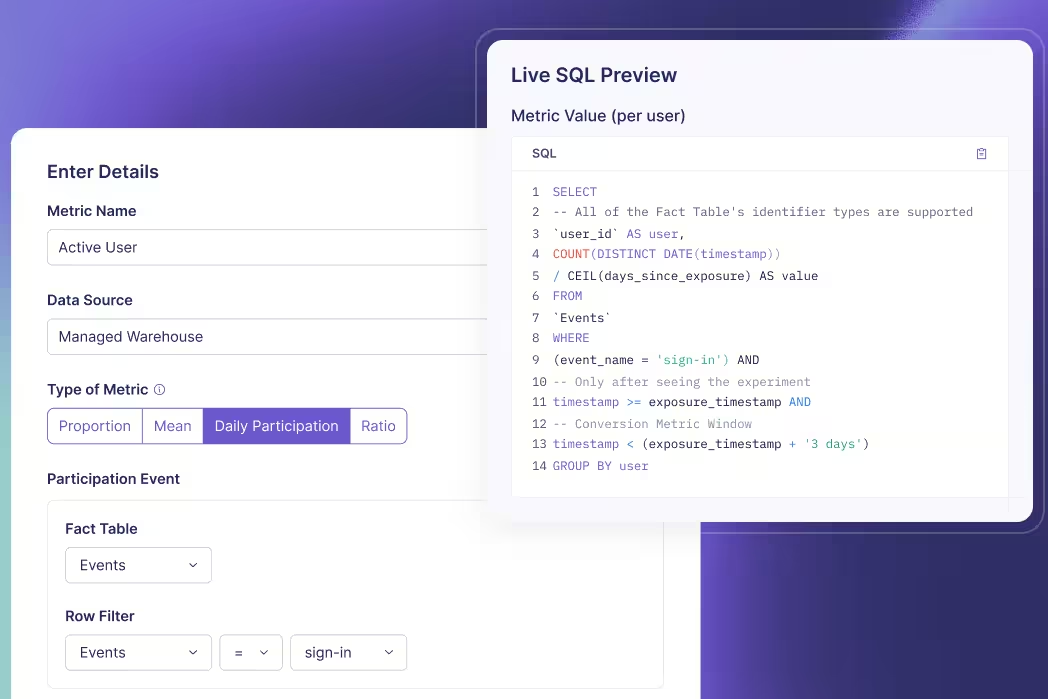
Use stronger controls for care-adjacent products
Some product changes are not clinical interventions but can still influence care. They need clinical ownership, narrower eligibility, conservative ramps, and explicit stopping criteria.
Clinician workflow support
A test might compare how a work queue prioritizes administrative follow-up, how a note template reduces documentation work, or how a non-diagnostic alert is presented. The treatment should not silently alter the clinical standard of care.
Randomize at the unit that prevents contamination. Individual clinician assignment may fail when teams share queues and handoffs; clinic- or unit-level clusters may better match the workflow. Measure task completion and time saved, with guardrails for missed work, overrides, escalations, documentation quality, and staff workload.
Preventive-care outreach
Compare approved outreach content or channels for people already eligible under the same clinical rule. Do not experiment with whether one group receives necessary care or required notice.
Use completed appropriate follow-up as the primary outcome. Track opt-outs, unreachable patients, scheduling capacity, disparities, complaints, and downstream cancellations. If the treatment drives demand beyond operational capacity, a messaging lift can make access worse.
Digital adherence support
Test the presentation or timing of an approved reminder, checklist, or educational cue. Avoid treatment changes that could be interpreted as personalized medical advice without the corresponding validation and oversight.
Measure the intended behavior with caution. Self-reported completion or app engagement is not a clinical outcome. Include adverse-event reporting, escalation pathways, disengagement, and privacy events where relevant.
Feature rollout in health software
Use feature flags to separate deployment from release, start with internal or trained cohorts, and expand only when technical and clinical guardrails remain healthy. GrowthBook’s feature flag platform supports targeted rollouts and kill switches, while the experiment layer measures impact.
The rollback plan must describe more than turning off a flag. Determine whether the old experience remains clinically and operationally safe, how queued work is reconciled, what happens to partial workflows, and who is authorized to stop exposure.
Protect data by design
Do not send a broad event stream to an experimentation vendor and decide later which fields were unnecessary. Inventory the data before implementation:
| Data question | Required decision |
|---|---|
| Assignment | What is the least identifiable stable unit that works? |
| Eligibility | Which sensitive attributes are truly needed? |
| Exposure | What event proves the treatment was delivered? |
| Outcomes | Can metrics be computed inside the governed data environment? |
| Access | Which roles can view assignments, segments, and results? |
| Retention | When are raw records, logs, and exports removed? |
The HHS minimum-necessary guidance describes limiting uses, disclosures, and requests for protected health information to what is needed for the intended purpose, with policies based on roles and recurring versus non-routine access. Apply that principle to experiment attributes, debugging logs, dashboards, and downloaded readouts.
Pseudonymous identifiers reduce exposure but do not automatically make a dataset non-sensitive or outside applicable rules. Review linkability, small cohorts, free-text fields, URLs, device metadata, and combinations that can reveal a condition. Never put clinical details or identifiers in feature names, variation labels, or URLs.
A warehouse-native experimentation approach can query approved metrics where the organization already governs them. Architecture does not create compliance on its own; teams still need contracts, access control, auditability, retention rules, security review, and configuration that matches the approved data flow.
Keep unsafe questions out of product experimentation
An experimentation policy should name prohibited or separately governed categories. Product teams should not discover the boundary only after a proposal reaches launch review.
Do not use an ordinary product A/B test to withhold a clinically indicated service, emergency direction, safety warning, accessibility accommodation, required disclosure, or legally protected choice. Do not reduce the visibility of risks to improve completion. Do not randomize a diagnostic or treatment recommendation without the clinical, regulatory, and research framework appropriate to that intervention.
Avoid treatments that exploit fear, urgency, shame, or uncertainty about health. A message can increase appointment conversion while undermining informed choice. Likewise, do not test whether patients tolerate a harder cancellation, more confusing privacy control, or hidden cost. Both variants must meet the organization’s baseline standard for respectful and comprehensible communication.
Clinical AI and decision-support changes need an evaluation program beyond a click-based A/B test. Validate the model offline, examine performance and failure modes across relevant populations, review human factors, and stage deployment with clinical monitoring. An online comparison may contribute evidence only after both treatments meet the safety threshold for exposure.
When an activity may be human-subjects research, follow the institution’s process before enrolling or exposing anyone. HHS research-oversight training states that covered non-exempt human-subjects research requires the applicable review and that informed consent requirements apply unless the IRB authorizes otherwise. The product team should preserve the determination, protocol version, approved treatment, and reporting obligations with the experiment record.
Finally, do not interpret lack of detected harm as proof of safety. Rare adverse events, small vulnerable groups, and outcomes that occur after the experiment window may be underpowered. Use prior evidence, incident monitoring, qualitative reports, and post-rollout surveillance alongside the randomized estimate.
Define patient-centered metrics and guardrails
Healthcare teams need more than a conversion scorecard. Build a measurement hierarchy:
- Primary outcome: the operational or patient-facing result that answers the decision.
- Process diagnostics: steps that explain why the treatment worked or failed.
- Safety guardrails: outcomes that trigger a stop or clinical review.
- Equity checks: predeclared groups where access or benefit could differ.
- Operational guardrails: staffing, wait time, rework, cost, and downstream capacity.
Define the practical threshold before launch. A statistically detectable change may be too small to justify implementation, and a neutral aggregate can hide meaningful harm in a protected or vulnerable group. At the same time, slicing results across many small subgroups increases false-positive risk and can expose sensitive attributes. Predeclare the equity questions that matter and use appropriate privacy and multiple-testing controls.
GrowthBook supports reusable fact tables and metrics so teams can keep definitions reviewable. Use a power analysis for the primary outcome and critical guardrails. If the required sample or duration is unrealistic, do not weaken the standard; use usability research, simulation, staged quality improvement, or a larger treatment contrast.
Create a healthcare experiment review packet
Before launch, the owner should provide one reviewable packet:
- purpose, hypothesis, and operational decision
- classification and required oversight determination
- affected population and exclusion criteria
- clinical, privacy, security, accessibility, and compliance approvals
- treatment screenshots or workflow diagrams
- assignment, exposure, and data-flow design
- primary outcome, diagnostics, guardrails, and equity checks
- sample plan and stopping rule
- rollout stages, monitoring owner, and rollback procedure
- patient or clinician communication plan, if applicable
- documentation and retention plan
Use an approval matrix that names accountable people. Product approval does not replace clinical approval; a privacy review does not settle human-subjects research status; and an IRB determination does not automatically approve the production security architecture.
The WHO clinical-trial best-practices guidance emphasizes ethical standards, regulatory considerations, patient-centered research, transparency, and stakeholder collaboration. Not every healthcare product experiment is a clinical trial, but high-risk work should inherit the same respect for people and evidence.
Build trust into the experimentation program
Start with reversible operational improvements where both experiences are already acceptable. Prove that the team can classify risk, minimize data, validate assignment, monitor safety, and document decisions before expanding scope.
Publish internal rules for what teams may test, what requires added review, and what is out of bounds. Maintain an experiment registry and audit trail. Record neutral and negative results so a new team does not repeat the same risky idea.
GrowthBook can support the controlled delivery and analysis layer through experimentation, feature flags, permissions, and warehouse-defined metrics. The organization remains responsible for the clinical, ethical, legal, privacy, and operational framework around every test.
In healthcare, speed is valuable only when the learning process protects the people whose behavior creates the data.
Build a governed test workflow
Connect controlled releases to reviewable metrics and decision rules while keeping healthcare data in your approved architecture.
Get Started With GrowthBook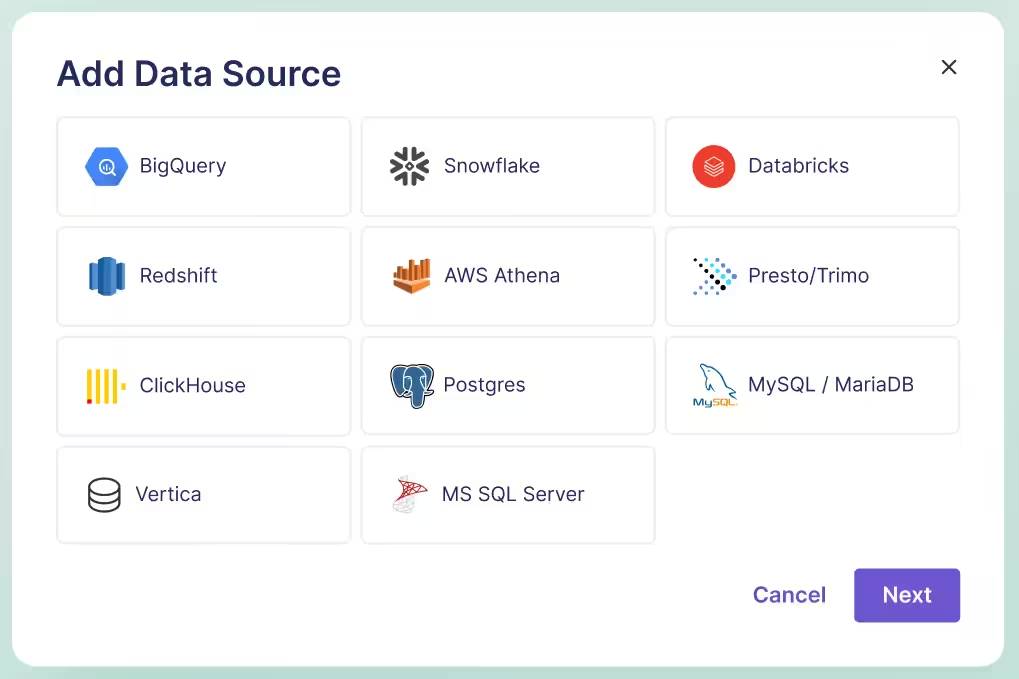
The right statistical test is determined by the question and data-generating process, not by which function is easiest to run. Start with the outcome, groups, and dependence structure; the test name comes later.
Z-tests, t-tests, chi-square tests, and analysis of variance (ANOVA) all compare observed data with a null model. They differ in the kind of outcome they model, the uncertainty they estimate, and the number or structure of groups they can compare.
For a simple product experiment, a useful first pass is:
- continuous outcome, two independent groups: usually a Welch two-sample t-test
- binary proportion, two large independent groups: a two-proportion z-test is common
- categorical counts across groups: chi-square test, if expected counts are adequate
- continuous outcome across three or more groups: one-way ANOVA or Welch ANOVA
Those rules are a starting point. Paired observations, clusters, ratios, repeated measures, heavy tails, covariate adjustment, or sequential monitoring require a model that reflects the design.
Choose from the outcome and hypothesis
Write the estimand before choosing a test. An estimand is the quantity the experiment is trying to estimate: a difference in mean revenue, a difference in conversion probability, or an association between two categorical variables.
| Question | Outcome | Common test |
|---|---|---|
| Did average order value change between A and B? | Continuous | Welch two-sample t-test |
| Did signup probability change between A and B? | Binary | Two-proportion z-test |
| Is plan choice associated with variant? | Categorical, 3+ levels | Chi-square test of independence |
| Do mean task times differ across four variants? | Continuous | One-way ANOVA |
| Did the same users' scores change before and after? | Paired continuous | Paired t-test |
The number of groups alone is insufficient. Conversion in four variants is still categorical data; a chi-square or binomial model may fit. Revenue in two groups is continuous; a t-test or regression is more natural.
The University of Michigan's statistical-test guide uses the same sequence: identify variable types and the relationship being tested before selecting a method.
When to use a z-test
A z-test compares a standardized estimate with the standard normal distribution. The classical one-sample z-test for a mean assumes the population standard deviation is known. That condition is unusual in product analytics, where variability is estimated from the current sample.
Z-tests remain common for proportions. In a two-arm conversion experiment, the estimate is:
Under the null of equal proportions and with adequate counts, the standardized difference is approximately normal. This yields a two-proportion z-test.
Use it when:
- the outcome is a binary count summarized as successes and failures
- assignment groups are independent
- sample sizes make the normal approximation credible
- the hypothesis and one- or two-sided direction were set before analysis
Do not rely on a universal “n greater than 30” rule. For rare events, 30 observations can produce almost no successes; for balanced common events, approximation quality can be good. Inspect expected successes and failures and use an exact or model-based method when counts are sparse.
In high-volume online experiments, a normal approximation is also used for many sample means through the central limit theorem. The important question is whether the estimator's sampling distribution and variance calculation are valid for the metric, not whether the raw user values look perfectly normal.
When to use a t-test
A t-test is designed for inference about means when the variance is estimated from sample data. That extra variance uncertainty produces a t distribution with heavier tails than the standard normal, especially at small sample sizes.
For two independent groups, default to Welch's t-test unless equal variance is justified. Welch's version does not assume the two population variances are equal and handles unequal group sizes. NIST's two-sample t-test reference shows the unequal-variance standard error based on each group's sample variance and size.
Use an independent two-sample t-test when:
- the outcome is numeric and the mean is the target
- the two groups contain different experimental units
- observations are independent within the model
- the mean and standard error behave well enough for the sample size
Use a paired t-test when each value has a meaningful partner: the same user's before-and-after score, or deliberately matched units. The analysis reduces each pair to a difference and tests the mean of those differences. Treating paired data as independent discards information and computes the wrong standard error.
The t-test can be sensitive to extreme values because the sample mean and variance are sensitive to them. Product metrics such as revenue or session duration are often skewed. At scale, the mean may still have a usable sampling distribution, but inspect outliers, data quality, and the estimand. Robust inference, transformations, winsorization policies, or bootstrap methods may be more appropriate when a few observations dominate the result.
Reduce variance before launch
Learn how CUPED and covariate adjustment can sharpen experiment estimates without changing the randomized comparison.
Explore Variance Reduction
When to use a chi-square test
Pearson's chi-square statistic compares observed category counts with counts expected under a null hypothesis. Two common forms are:
- goodness of fit: does one categorical distribution match specified probabilities?
- independence or homogeneity: is a categorical outcome distributed the same way across groups?
Suppose an onboarding experiment records three outcomes: completed, skipped, and abandoned. Cross-tabulate outcome by variant. A chi-square test asks whether the outcome distribution is independent of variant.
The test statistic sums (observed - expected)^2 / expected across cells. NIST's chi-square documentation describes the same comparison of binned frequency distributions.
Use a chi-square test when observations contribute counts to mutually exclusive categories and expected cell counts are large enough for the asymptotic approximation. With sparse cells, combine categories only when substantively justified or use an exact method such as Fisher's exact test for a two-by-two table.
A chi-square result says the distributions differ somewhere. It does not provide the most decision-friendly effect estimate by itself. Report category proportions, absolute differences, uncertainty intervals, and the cells contributing to the pattern.
For a binary two-arm experiment, the Pearson chi-square test and a two-sided two-proportion z-test are closely related: under standard conditions, the chi-square statistic with one degree of freedom equals the squared z statistic. Choose the representation that matches the hypothesis and reporting needs.
When to use ANOVA
ANOVA compares variation between group means with unexplained variation within groups. A one-way ANOVA tests the null that all population means are equal across levels of one factor.
Use it for a continuous outcome across three or more independent groups when the global question is whether any mean differs. Classical ANOVA assumes independent errors, normally distributed residuals within the model, and equal variances. Welch ANOVA relaxes the equal-variance assumption; R's 0 implements that approximation.
ANOVA's F-test is an omnibus test. A significant result means at least one mean differs, but it does not identify which one. Use planned contrasts or multiplicity-aware post-hoc comparisons to answer the product question.
ANOVA is more than a rule for “three or more groups.” Multi-factor ANOVA can estimate main effects and interactions in multivariate or factorial experiments. Repeated-measures or clustered data need corresponding error structures rather than a basic one-way calculation.
Why several t-tests are not a substitute for ANOVA
With four variants there are six pairwise comparisons. Testing each at 0.05 creates multiple opportunities for a false positive. An omnibus ANOVA tests one global null first, and planned follow-ups can use Tukey, Holm, Bonferroni, or another procedure appropriate to the family of claims.
The Bonferroni correction is simple and conservative. The right procedure depends on whether the goal is all pairwise comparisons, treatments versus one control, or a small set of preplanned contrasts. Define that family before looking at the ranking.
ANOVA and regression are also two views of the same linear-model machinery. R's 0 documentation describes aov as a wrapper around linear models for experimental designs. Regression is often more flexible when the analysis includes covariates, interactions, or unbalanced data.
Assumptions that change the choice
Before running any of the four tests, verify:
Independence and assignment unit
If the experiment randomizes accounts but analyzes users as independent observations, standard errors will usually be too small. Analyze at the randomization unit or use cluster-aware inference. If users can appear in both groups, repair the assignment or use a model that represents the dependence.
Paired or repeated observations
The same user measured twice is not two independent users. Use a paired test or repeated-measures model. For experiments with many events per user, aggregate to the user level or use appropriate clustered methods.
Outcome distribution and metric construction
Check missingness, zero inflation, extreme tails, ratio denominators, and censoring. A test can be mathematically correct for the supplied numbers while the metric itself misrepresents the user outcome.
Variance assumptions
Prefer Welch's t-test or Welch ANOVA when group variances may differ. Equal sample sizes do not prove equal variance, and a preliminary variance test can introduce another decision layer.
Sample size and sparse cells
Approximate z and chi-square methods need enough information in the relevant cells. Low-frequency guardrails and small segments may need exact methods or longer collection.
A product experimentation decision tree
Use this sequence before opening a statistics package:
- What unit was randomized: user, account, device, session, or region?
- What is the primary estimand: mean, proportion, category distribution, or model coefficient?
- Are groups independent, paired, repeated, or clustered?
- Are there two groups, several groups, or multiple factors?
- Do expected counts and sample sizes support the approximation?
- Are variances, tails, or outliers likely to break the default model?
- How many confirmatory hypotheses can trigger the decision?
- Was the test direction and stopping rule declared before launch?
Then choose the simplest model that answers the exact question. A two-proportion z-test may be perfect for signup conversion, while a t-test handles mean revenue and a chi-square test handles plan mix in the same experiment. Different metrics can require different tests.
Report effects, not only test names
The test produces a statistic and p-value under a null model. The guide to interpreting a t-test p-value shows why that number needs the effect, interval, and degrees of freedom beside it. The product decision needs more:
- the effect estimate in business units
- a confidence or credible interval
- sample sizes and allocation
- baseline and treatment values
- assumption and data-quality checks
- the planned hypothesis family
- practical thresholds and guardrails
GrowthBook's statistics documentation explains the frequentist and Bayesian engines available for experiment analysis. Whichever framework is used, review effect magnitude and uncertainty together. A small p-value can accompany a trivial lift in a huge sample, while a valuable estimated lift can remain uncertain in a small one.
Choose the test by tracing the data back to the experiment design. For three or more continuous-outcome variants, the deeper ANOVA guide covers the omnibus F-test, planned contrasts, and Welch alternative. When the outcome, assignment unit, dependence, and hypothesis are explicit, the difference between z, t, chi-square, and ANOVA becomes a modeling decision rather than a memorization exercise.
Analyze tests with context
Connect experiment assignments to trusted metrics, inspect uncertainty, and keep decision rules visible to the whole team.
Get Started With GrowthBookAn experiment with control plus three variants creates more than one comparison. ANOVA gives the team one principled global test of whether the variants differ before it starts hunting for a winner.
Analysis of variance, or ANOVA, is a family of statistical models for comparing group means and decomposing sources of variation. In a one-way product experiment, the “factor” is the assigned variant and its “levels” are control, B, C, and D.
The basic ANOVA question is deliberately broad: if all variants had the same population mean, would the observed separation among their sample means be surprising relative to the noise within variants?
That question is useful, but incomplete. A significant ANOVA result does not say which variant won, whether the lift is large enough to ship, or whether assumptions and instrumentation are sound. Those conclusions require planned contrasts, uncertainty intervals, and experiment-quality checks.
How ANOVA compares means through variance
ANOVA separates total variability into components:
- between-group variation: how far each group mean is from the overall mean
- within-group variation: how far individual observations are from their group mean
Each sum of squares is divided by its degrees of freedom to produce a mean square. The F statistic is:
Under the null hypothesis that all group means are equal, both quantities estimate the same underlying error variance, so their ratio should often be near 1. When group means are separated relative to the residual noise, F grows.
NIST's one-way ANOVA explanation describes this as comparing the level mean square with the residual mean square. The p-value is the probability, under the null model and assumptions, of an F statistic at least as large as the observed one.
For k groups and N total observations, one-way ANOVA usually has:
The numerator asks how much the k means vary. The denominator pools information about variability inside the groups.
A four-variant experiment example
Suppose a SaaS team tests four onboarding flows and measures projects created per eligible account during the first week.
| Variant | Accounts | Mean projects | Standard deviation |
|---|---|---|---|
| Control | 1,000 | 2.30 | 1.80 |
| B | 1,020 | 2.42 | 1.84 |
| C | 990 | 2.61 | 1.91 |
| D | 1,010 | 2.36 | 1.79 |
The null hypothesis is:
The alternative is that not all four means are equal. Notice what it does not say: “C is best.” The global alternative includes any pattern where at least one mean differs.
If the F-test rejects the null, the team should evaluate the comparisons it planned. It might compare every treatment with control, or test one contrast between the current flow and the average of three new concepts. The comparison plan should reflect the decision, not the visual ranking in the finished dashboard.
Make multiple tests trustworthy
See how experimentation leaders plan hypotheses, guardrails, and review practices when a result surface contains many possible claims.
Watch the Trustworthy Experiments Talk
Why not run every pairwise t-test?
Four groups create six pairs. If the team runs six independent tests at alpha 0.05 and treats any significant result as proof, the probability of at least one false positive across the family can exceed 0.05.
ANOVA gives one global test of the equality of all means. It also estimates residual variation using all groups, which can be more efficient than estimating it afresh for each pair under the classical equal-variance model.
The global test does not eliminate multiplicity in follow-up comparisons. R's Tukey HSD documentation explicitly notes that ordinary t-tests inflate the probability of a false declaration across a family. Choose the follow-up procedure for the comparisons the decision actually needs:
- every pair: Tukey-style simultaneous comparisons
- every treatment versus control: Dunnett-style comparisons
- a few planned product questions: predeclared contrasts with a suitable adjustment
- a conservative small family: a Bonferroni or Holm correction
An omnibus test can also be nonsignificant while one carefully planned contrast is persuasive, because the hypotheses and power differ. Decide before launch whether the global null or a treatment-versus-control contrast is the primary decision test.
Unequal group sizes do not automatically invalidate ANOVA, but they make the variance assumption and contrast plan more consequential. If allocation is intentionally uneven, power the smallest comparison that drives the decision and preserve the assignment probabilities. When variances and sample sizes both differ, classical pooled ANOVA can behave poorly; Welch ANOVA or a regression with suitable standard errors is usually easier to defend.
Planned contrasts can also use product structure that the global test ignores. Instead of comparing every pair, a team might compare control with the average of three related treatments, or compare two low-intensity treatments with two high-intensity treatments. A small set of predeclared contrasts often answers the business question with more power and clearer multiplicity control than an exhaustive winner search.
ANOVA assumptions in experiments
The familiar one-way fixed-effects model can be written as:
Classical inference depends on the residuals and design, not on a requirement that the combined raw outcome form one bell curve. NIST's model reference assumes independent, normally distributed errors with mean zero and common variance.
Independent observations
The analysis unit must respect randomization. If accounts are assigned but every user within an account is treated as independent, the standard error ignores clustering. Aggregate at the account level or use cluster-robust or hierarchical methods.
Repeated events from one user create the same problem. Ten sessions from one user do not carry the same independent information as ten users.
Appropriate residual behavior
ANOVA is often robust to moderate non-normality with balanced, sufficiently large groups, but severe skew, outliers, censoring, or zero inflation can make the mean unstable or the F approximation unreliable. Diagnose residuals and assess whether the mean is still the business estimand.
Equal variance for classical one-way ANOVA
Classical ANOVA assumes a common population variance. This can fail when a treatment changes both the mean and spread, or when groups serve different traffic mixes. Unequal group sizes make the problem more consequential.
SciPy's 0 supports Welch ANOVA when equal_var=False. Welch's method relaxes equal population variances and adjusts the degrees of freedom.
Correct outcome model
ANOVA targets a continuous mean. Conversion is binary; event counts are discrete; time-to-churn can be censored. Large-sample mean inference can sometimes work, but logistic, Poisson or negative-binomial, survival, or other generalized models may better represent the outcome and produce interpretable effects.
One-way, two-way, and repeated-measures ANOVA
“ANOVA” names a family rather than one calculation.
One-way ANOVA
One categorical factor with multiple levels, such as four assigned onboarding variants. This is the usual A/B/n example.
Two-way or factorial ANOVA
Two controlled factors, such as headline and layout. The model estimates each main effect plus their interaction. The interaction asks whether one factor's effect changes with the other. This is central to a properly designed multivariate test.
Repeated-measures ANOVA
The same units are observed under multiple conditions or times. Dependence is part of the design and must be modeled. A basic independent one-way ANOVA is invalid for repeated measurements.
ANCOVA
Analysis of covariance adds continuous covariates to the group comparison. In randomized experiments, pre-experiment covariates can improve precision when they are chosen and measured without post-treatment contamination. GrowthBook's guide to variance reduction explains the same motivation in online experimentation.
Run one-way ANOVA in Python
At the action boundary, keep one numeric observation per independent analysis unit in each group. In SciPy:
Before running it, confirm that rows match the randomization unit and missing values have a documented policy. Afterward, inspect group summaries and residual behavior. The p-value alone cannot reveal a broken exposure join or a few enormous outliers.
In R, aov(outcome ~ variant, data = experiment) fits the classical model. R documents 1 as a linear-model interface, which helps explain why ANOVA, regression, and contrasts are closely connected.
Interpret the ANOVA table
A standard output contains:
- degrees of freedom
- sum of squares
- mean square
- F statistic
- p-value
Suppose the output reports F(3, 4016) = 6.8, p < 0.001. Under the model, the observed ratio of between-variant to within-variant variation is unlikely if all four population means are equal. It does not mean every treatment beats control or that any effect is commercially important.
Add the quantities the product decision needs:
- each mean and sample size
- differences from control in original units
- simultaneous or comparison-specific intervals
- an effect-size measure when useful
- guardrail and data-quality results
- the follow-up comparison method
Avoid ranking noisy means without uncertainty. The highest observed variant has benefited from both its true effect and sampling variation, especially when many variants were screened.
Common ANOVA mistakes
Treating events as independent users
Repeated events make the nominal sample size huge and uncertainty too narrow. Preserve the assignment unit.
Using ANOVA for every metric shape
The word “variant” does not imply ANOVA. Match the outcome distribution and estimand to a model.
Checking assumptions after selecting a winner
Write the model, outlier policy, transformation, and variance choice before the ranking is visible. Result-driven switching creates hidden researcher degrees of freedom.
Treating a significant F-test as a winner declaration
Follow with the planned contrasts. The omnibus test only rejects equality of all means.
Ignoring practical significance
A very large experiment can detect a tiny difference. Compare intervals with a minimum practical effect and account for implementation cost and guardrails.
Use ANOVA as part of an experiment plan
Before launch, specify the factor and levels, independent unit, primary continuous outcome, minimum effect, sample-size plan, variance assumption, global or contrast hypothesis, comparison family, and stopping rule.
Then verify assignment and exposure before interpreting the model. A sample ratio mismatch can signal that observed group counts no longer reflect the planned randomization. No F-test can repair biased exposure data.
ANOVA is valuable because it turns a field of variant means into a structured model of signal and noise. The broader z-test, t-test, chi-square, and ANOVA guide shows when the outcome and hypothesis call for another member of that family. Use the omnibus test for the global question, planned contrasts for the decision, and effect estimates for practical judgment. That sequence makes a multiple-variant test easier to defend than a dashboard full of uncoordinated p-values.
Compare variants with discipline
Run controlled experiments, connect trusted metrics, and review treatment effects and uncertainty in one shared workflow.
Start With GrowthBookReady to ship faster?
No credit card required. Start with feature flags, experimentation, and product analytics—free.